<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://sachinjoseph.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://sachinjoseph.com/" rel="alternate" type="text/html" hreflang="en" /><updated>2026-10-02T22:48:00+00:00</updated><id>https://sachinjoseph.com/feed.xml</id><title type="html">Sachin Joseph</title><subtitle>Notes on software engineering, developer tools, AI and machine learning fundamentals, and whatever I&apos;m currently digging into.</subtitle><entry><title type="html">Embeddings — LLMs Part 5</title><link href="https://sachinjoseph.com/posts/embeddings/" rel="alternate" type="text/html" title="Embeddings — LLMs Part 5" /><published>2026-10-02T05:46:09+00:00</published><updated>2026-10-02T22:47:36+00:00</updated><id>https://sachinjoseph.com/posts/embeddings</id><content type="html" xml:base="https://sachinjoseph.com/posts/embeddings/"><![CDATA[<h2 id="the-definition">The Definition</h2>

<p>An <strong>embedding</strong> is a list of numbers that represents one token’s meaning. That list is also called a <strong>vector</strong> — an ordered list of numbers, nothing more.</p>

<p>Here <strong>meaning</strong> has a narrow sense: how a token gets used — the kinds of sentences it appears in — not anything about the real world.</p>

<p>The same token always gets the same vector, no matter where it appears. Special tokens get vectors too — the end-of-sequence token from <a href="/posts/tokens-not-words/">Part 3</a> is one of them.</p>

<p>Every token in the vocabulary (<a href="/posts/tokens-not-words/">Part 3</a>) gets its own vector. Picture the <strong>embedding table</strong> — one <strong>row</strong> per token: a token’s position in the vocabulary is its row number, which is exactly its token ID. Turning a token into its vector is a lookup, not a calculation — and not a dictionary/hash search either: the token ID is already an integer row number, so retrieving its row is direct array indexing, the same constant-time operation as indexing into any array by position. The network stores one vector per vocabulary entry — these stored vectors are part of the network’s own parameters (<a href="/posts/what-a-neural-network-actually-is/">Part 2</a> covered weights and biases; embeddings are the other kind) — and retrieves the right one. <a href="/posts/paper-byte-pair-encoding/">Part 4</a>’s tokenizer spells every input from known pieces, with no generic “unknown” token — so every ID the lookup ever receives already has its own row.</p>

<p>A few illustrative rows make this concrete — invented numbers, not an actual model’s real weights. The table itself stores only the vector column; the row number <em>is</em> the token ID, not a separately stored value, and the token spelling isn’t stored in this table at all — that mapping lives in the vocabulary (<a href="/posts/tokens-not-words/">Part 3</a>/<a href="/posts/paper-byte-pair-encoding/">Part 4</a>) instead. “Row” and “Token” are shown here only so the table is readable:</p>

<table>
  <thead>
    <tr>
      <th>Row (= token ID)</th>
      <th>Token (not stored here — shown for reference)</th>
      <th>Vector</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td><code class="language-plaintext highlighter-rouge">cat</code></td>
      <td>0.22, 0.68, …</td>
    </tr>
    <tr>
      <td>2</td>
      <td><code class="language-plaintext highlighter-rouge">dog</code></td>
      <td>0.42, 0.80, …</td>
    </tr>
    <tr>
      <td>3</td>
      <td><code class="language-plaintext highlighter-rouge">car</code></td>
      <td>0.82, 0.22, …</td>
    </tr>
  </tbody>
</table>

<p>A real table has one row per vocabulary entry — 50,257 of them for GPT-2 — and hundreds or thousands of numbers per row, not two; this is trimmed down to show the shape:</p>

<pre><code class="language-mermaid">flowchart LR
    T["token"] --&gt;|"position in&lt;br/&gt;vocabulary"| ID["token ID"]
    ID --&gt;|"lookup"| V["vector&lt;br/&gt;(embedding)"]

    accTitle: Looking up a token's embedding
    accDescr: A token maps to its token ID by position in the vocabulary, and that ID is used to look up its vector, the embedding, from a stored table.
</code></pre>

<h2 id="where-this-fits-in-the-pipeline">Where This Fits in the Pipeline</h2>

<p>This lookup isn’t a separate phase — it’s the network’s own first move, every single time. It happens right after tokenization and right before the network’s first layer (<a href="/posts/what-a-neural-network-actually-is/">Part 2</a>) does anything with the result, for every token: the ones in the original prompt, and every token the model generates and feeds back in during the loop <a href="/posts/tokens-not-words/">Part 3</a> described:</p>

<pre><code class="language-mermaid">flowchart TB
    TOK["prompt tokens&lt;br/&gt;(Part 3)"] --&gt;|"whole prompt"| EMB["embedding lookup&lt;br/&gt;(this post)"]
    EMB --&gt;|"append"| VSEQ["vector sequence"]
    VSEQ --&gt; NET["network layers&lt;br/&gt;(Part 2)"]
    NET --&gt;|"one final vector"| SCORE["scored against&lt;br/&gt;every row&lt;br/&gt;(this post)"]
    SCORE --&gt;|"highest score wins"| ID["winning row:&lt;br/&gt;next token ID"]
    ID --&gt;|"new token"| EMB
    ID --&gt;|"looked up in&lt;br/&gt;vocabulary (Part 3/4)"| TXT["next token&lt;br/&gt;(output text)"]

    accTitle: Where embedding lookup sits in the pipeline
    accDescr: Prompt tokens are embedded and appended to the vector sequence; the vector sequence feeds the network's layers; the layers produce one final vector, scored against every row to find the highest-scoring row; that winning row, the next token's ID, is embedded and appended to the vector sequence to continue generation, and separately looked up in the vocabulary to produce the actual output text.
</code></pre>

<p>The box labeled <strong>vector sequence</strong> only ever grows one way: a fresh vector comes out of the embedding lookup and gets appended to it — nothing ever removes from it or rewrites an entry already there. The prompt fills it in first, one vector per prompt token; after that, each loop appends exactly one more vector, for whichever token the model most recently generated. That’s the “new token joins what’s already there” moment made concrete: the new vector joins the sequence, and the whole sequence — not just the newest entry — is what feeds the network every time.</p>

<p>The lookup itself never runs twice for the same position: the embedding step is a pure function of the token ID, the same token always returns the same row, so a vector already in the sequence is never looked up again — appending is the only thing that ever happens to it. What <em>does</em> reprocess the whole sequence each step is the network layers next in line: attention-based layers mix information across positions, so their output can only be computed correctly by running over every vector present, old and new together — that’s <a href="/posts/what-a-neural-network-actually-is/">Part 2</a>’s territory (and a future post’s<!-- Part 7 -->), not the embedding step’s.</p>

<p>“New” here means new <em>to the vector sequence</em>, not new to the table — the table never grows; only the sequence does. Scoring only ever picks among the table’s existing rows (that’s what “scored against every row” means above), so the winning ID is guaranteed to already have a row: it has to be one of the same fixed set the table was built with at training time, the same set <a href="/posts/paper-byte-pair-encoding/">Part 4</a>’s tokenizer already guarantees covers every possible input.</p>

<p>The winning ID is then used two independent ways at once, neither waiting on the other: fed back to continue generation, and separately looked up in the vocabulary to produce visible text. Generation doesn’t pause to produce that text, and producing the text doesn’t wait for the next generation step.</p>

<p>The lookup only cares which token it is, not where in the sentence it appears. The same token gets the same vector whether it’s the first word or the last — word order gets added afterward, in a future post<!-- Part 9 -->.</p>

<p>One spelling gets one row even when it has two meanings: <code class="language-plaintext highlighter-rouge">bank</code> the riverbank and <code class="language-plaintext highlighter-rouge">bank</code> the money store start from the same vector. That starting vector doesn’t stay frozen, though. Each layer revises it using the surrounding tokens. A future post<!-- Part 9 --> covers that mechanism — which is also how the two <code class="language-plaintext highlighter-rouge">bank</code>s get told apart downstream.</p>

<p>Training, covered in a future post<!-- Part 13 -->, is what shapes the vectors themselves — it adjusts them the same way it adjusts any other parameter. By the time the model is generating text, the vectors are already fixed, and this step is retrieval, nothing more.</p>

<p>Many models, including <a href="https://huggingface.co/docs/transformers/model_doc/gpt2">GPT-2</a>, use that same table a second time. Scoring every possible next token (<a href="/posts/what-is-a-language-model/">Part 1</a>) means comparing the network’s output to every vocabulary entry’s vector — and rather than learning a whole separate set of vectors for that, the model reuses the same embedding table, applied in reverse: rows read out as comparisons instead of looked up by ID. Each row gets one score for how well it matches the output — computed by multiplying the output’s coordinates with the row’s matching coordinates and adding the results up — and the highest score wins. Reusing one table for both jobs is called <a href="https://arxiv.org/abs/1608.05859"><strong>weight tying</strong></a>; it saves a whole second table’s worth of parameters.</p>

<p>That scoring isn’t a loop over rows, one at a time — it’s a single <strong>matrix multiplication</strong>. The embedding table is already a matrix, one row per vocabulary entry; multiplying that matrix by the output vector produces exactly one number per row in one operation, and each of those numbers is precisely the row-by-row multiply-and-add score described above. A tiny, illustrative version, reusing the 3-row table above and a made-up 2-number output vector <code class="language-plaintext highlighter-rouge">[0.4, 0.8]</code>:</p>

<table>
  <thead>
    <tr>
      <th>Row</th>
      <th>Vector</th>
      <th>Score (vector × output, added up)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cat</code></td>
      <td>0.22, 0.68</td>
      <td>0.22×0.4 + 0.68×0.8 = 0.63</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">dog</code></td>
      <td>0.42, 0.80</td>
      <td>0.42×0.4 + 0.80×0.8 = 0.81</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">car</code></td>
      <td>0.82, 0.22</td>
      <td>0.82×0.4 + 0.22×0.8 = 0.50</td>
    </tr>
  </tbody>
</table>

<p>All three scores come out of that one multiplication; <code class="language-plaintext highlighter-rouge">dog</code> wins because its vector was the closest match to the made-up output vector. A real model runs this same arithmetic across all 50,257 rows and 768 numbers per row at once — the scale changes, the operation doesn’t.</p>

<p>The winning row’s <em>number</em> is the model’s actual output here, not text — row 2 scoring highest doesn’t hand the model the word “dog” directly, it hands it “row 2.” Since the embedding table never stored the token spelling in the first place, turning that row number into the text <code class="language-plaintext highlighter-rouge">dog</code> is a separate step done afterward, by looking the ID up in the tokenizer’s vocabulary (<a href="/posts/tokens-not-words/">Part 3</a>/<a href="/posts/paper-byte-pair-encoding/">Part 4</a>) — the same vocabulary as the embedding table’s rows, used in the opposite direction from how tokenizing an input works: text in, ID out there; ID in, text out here.</p>

<h2 id="how-it-works">How It Works</h2>

<p>Each vector has many numbers in it, and real models vary a lot: <a href="https://huggingface.co/docs/transformers/model_doc/gpt2">GPT-2</a> uses 768, Llama 2’s 7-billion-parameter model uses <a href="https://huggingface.co/docs/transformers/model_doc/llama2">4,096</a>, and GPT-3’s largest model uses <a href="https://arxiv.org/abs/2005.14165">12,288</a>. Each number is one coordinate in a space with that many dimensions — called a <strong>vector space</strong>. Two tokens with similar meaning end up with similar vectors: close together in that space. Two unrelated tokens end up far apart. Closeness isn’t something the model sees — it’s something it computes, with the same multiply-and-add as scoring: multiply the two vectors’ matching coordinates and add the results up. A big total means close together; a small one means far apart.</p>

<p>Multiply vocabulary size by dimension count and the scale becomes concrete: GPT-2’s vocabulary (<a href="/posts/paper-byte-pair-encoding/">Part 4</a>) has 50,257 entries, each needing its own 768-number vector — about 38.6 million numbers in this one table alone, before the rest of the network’s own layers (<a href="/posts/what-a-neural-network-actually-is/">Part 2</a>) add any parameters of their own.</p>

<p>Simplified to two coordinates so it can be drawn, the <em>idea</em> looks like this. Read only the distances between the dots:</p>

<pre><code class="language-mermaid">%%{init: {"quadrantChart": {"pointTextFontSize": 20}}}%%
quadrantChart
    title Relative distances only
    x-axis " " --&gt; " "
    y-axis " " --&gt; " "
    cat: [0.22, 0.68]
    dog: [0.42, 0.8]
    car: [0.82, 0.22]

    accTitle: cat and dog close together, car far apart
    accDescr: A simplified 2-coordinate plot: cat and dog as nearby points, car as a distant point. Only the relative distances between points carry meaning.
</code></pre>

<p><code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">dog</code> land near each other; <code class="language-plaintext highlighter-rouge">car</code> lands far from both. A real embedding uses hundreds or thousands of coordinates, not two, which is what lets it capture far more relationships than “close” or “far” in a simple picture can show.</p>

<p>One thing the simplified picture can’t show honestly: unlike its x and y axes, a real embedding’s individual coordinates don’t each stand for a nameable property like size or color. No single number says “how much of a pet this is.” Meaning lives in the whole vector together — spread across every coordinate at once, not pinned to any one of them.</p>

<h2 id="where-the-closeness-comes-from">Where the Closeness Comes From</h2>

<p>No one, and nothing, explicitly decides that <code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">dog</code> should be close. The vectors start as random numbers, the same way every other parameter in the network does (<a href="/posts/what-a-neural-network-actually-is/">Part 2</a>) — before training, <code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">car</code> are no closer together than <code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">dog</code> are. Training, covered in a future post<!-- Part 13 -->, is the only thing that ever touches these numbers again, and closeness isn’t something it’s ever directly told to produce — it’s a side effect of the specific task those vectors get trained on.</p>

<p>The classic approach, covered in full in a future post<!-- Part 6 -->, trains each token’s vector to help predict the words that tend to appear near it in real text. <code class="language-plaintext highlighter-rouge">cat</code> and <code class="language-plaintext highlighter-rouge">dog</code> show up in a lot of the same kinds of sentences — “I fed my <em>__,” “the __</em> ran across the yard” — so the easiest way for training to get better at predicting those surrounding words for both tokens is to give them similar vectors, so the same downstream computation works for either one. <code class="language-plaintext highlighter-rouge">car</code> never shows up in those same contexts, so nothing pulls its vector anywhere near them.</p>

<p>This is sometimes called the <em>distributional hypothesis</em>: words used in similar contexts tend to mean similar things. Training doesn’t know anything about meaning directly — it only ever reduces prediction error on whatever task it’s given — but reducing prediction error on a context-prediction task happens to produce vectors that line up with meaning as a side effect.</p>

<h2 id="why-embeddings-matter">Why Embeddings Matter</h2>

<p>Once meaning is a list of numbers, “how similar are these two tokens” becomes a plain math question — the distance between two vectors — instead of something a program has to be told by hand.</p>

<p>This pays off directly in generation. Raw token IDs (<a href="/posts/tokens-not-words/">Part 3</a>) carry no relationship information at all — if <code class="language-plaintext highlighter-rouge">cat</code> happened to be token 4187 and <code class="language-plaintext highlighter-rouge">dog</code> token 9341, those numbers alone would say nothing about each other. Embeddings fix that: whatever the network has learned about handling <code class="language-plaintext highlighter-rouge">cat</code> in a given context transfers to <code class="language-plaintext highlighter-rouge">dog</code> almost for free, since their nearby vectors mean the same downstream computation treats them similarly. Everything downstream in the network, including attention, covered in a future post<!-- Part 7 -->, operates on these vectors, not on the original text — so that transfer happens automatically, every layer, without the model needing to have seen every word combination during training to produce coherent output. These same vectors also get reused outside the model entirely — for finding documents by meaning, covered in a future post<!-- Part 44 -->.</p>

<hr />
<p><em>Next: Paper: word2vec — the paper that showed meaning could be learned this way. (Coming soon.)</em></p>

<p><em>This post uses “training”<!-- Part 13 --> and “attention”<!-- Part 7 --> loosely — covered in future posts.</em></p>]]></content><author><name></name></author><category term="AI" /><category term="AI" /><category term="LLM" /><category term="Machine Learning" /><category term="Embeddings" /><summary type="html"><![CDATA[An embedding is a list of numbers that represents one token's meaning. That list is also called a vector — an ordered list of numbers, nothing more.]]></summary></entry><entry><title type="html">Paper: Byte Pair Encoding — LLMs Part 4</title><link href="https://sachinjoseph.com/posts/paper-byte-pair-encoding/" rel="alternate" type="text/html" title="Paper: Byte Pair Encoding — LLMs Part 4" /><published>2026-09-30T23:13:12+00:00</published><updated>2026-10-02T06:20:37+00:00</updated><id>https://sachinjoseph.com/posts/paper-byte-pair-encoding</id><content type="html" xml:base="https://sachinjoseph.com/posts/paper-byte-pair-encoding/"><![CDATA[<p><em>Sennrich, Haddow &amp; Birch, <a href="https://arxiv.org/abs/1508.07909">“Neural Machine Translation of Rare Words with Subword Units”</a> (2015)</em></p>

<h2 id="the-problem">The Problem</h2>

<p>A model with a fixed vocabulary (<a href="/posts/tokens-not-words/">Part 3</a>) can’t handle a word it has never seen — a made-up word, a rare name, a typo. Before this paper, tokenizers often replaced that word with a generic “unknown” token, throwing the information away.</p>

<h2 id="the-core-idea">The Core Idea</h2>

<p>Instead of a vocabulary of whole words, build one out of frequently occurring pieces, so any word — seen before or not — can be spelled using pieces the model does know.</p>

<p>Characters alone would already solve that problem — every possible piece already exists, nothing is ever truly unseen. The real cost is length: a model reads and predicts one token at a time, so spelling ordinary text out one character at a time multiplies how many steps that takes, for text that’s already easy to say more compactly (<a href="/posts/tokens-not-words/">Part 3</a>). Merging trades some of that flexibility back for efficiency: common sequences collapse into single tokens, so ordinary text stays short, while anything the training data never saw still falls back to individual characters instead of breaking entirely.</p>

<p>The paper adapted <strong>byte pair encoding (BPE)</strong>, an older data-compression algorithm, to build this piece vocabulary. BPE starts with every individual character as its own token, then repeatedly finds the <em>most frequent adjacent pair</em> of tokens in the training text and merges that pair into one new token, built entirely from data instead of a hand-written word list.</p>

<p>The algorithm has exactly one real setting: how many merges to run. More merges builds a larger vocabulary of longer, more specific pieces; fewer merges builds a smaller vocabulary of shorter, more general ones. The final vocabulary size is the starting character count plus however many merges were run — a direct knob on the tradeoff <a href="/posts/tokens-not-words/">Part 3</a> described between vocabulary size and how finely words get split.</p>

<p>Vocabulary size and the length of any one piece of text are two different numbers, worth keeping separate. Vocabulary size only grows — every merge adds one more entry, and nothing already in the vocabulary is ever removed. How many tokens it takes to spell a specific word goes the other way: before “l” and “o” ever merge, “low” costs 3 tokens; once enough merges have happened, it costs 1. A bigger vocabulary is exactly what makes shorter token sequences possible — the two numbers move in opposite directions on purpose.</p>

<p>Those old entries stay for a reason: a merge only helps in the exact context it was learned in. “l” merging with “o” only pays off when an “l” is actually followed by an “o” — words like “lamp” or “jungle” have an “l” that isn’t, and still need the standalone “l” token to be spelled at all. Deleting “l” and “o” once “lo” existed would break the one guarantee the whole algorithm is built on: any input can always be tokenized, worst case one character at a time.</p>

<p>That number isn’t something the algorithm works out on its own — like a model’s size, it’s chosen ahead of time by whoever trains the tokenizer, then fixed for that vocabulary’s whole lifetime. The paper itself tested merge counts in the tens of thousands (59,500 for a single-language vocabulary, 89,500 for a shared vocabulary across two languages) and kept whichever produced the best translation quality on held-out data. In practice today, a new project is more likely to start from an existing model’s vocabulary size, like GPT-2’s 50,000, than to re-run that search from scratch.</p>

<p>One more detail matters for correctness. The algorithm marks where each word ends (commonly written <code class="language-plaintext highlighter-rouge">&lt;/w&gt;</code>) before counting pairs, so a piece like “est” at the end of a word (“widest”) is tracked separately from the same two letters appearing mid-word (“establish”) — without that marker, the algorithm would wrongly treat both as the same recurring pair and merge them together.</p>

<h2 id="learning-the-vocabulary">Learning the Vocabulary</h2>

<p>Training repeats one simple loop until the vocabulary reaches its target size:</p>

<pre><code class="language-mermaid">flowchart LR
    A["count every adjacent&lt;br/&gt;pair across the training text"] --&gt; B["merge the single&lt;br/&gt;most frequent pair&lt;br/&gt;into one new token"]
    B --&gt; C["↺ repeat, using the&lt;br/&gt;updated text, until&lt;br/&gt;target vocab size is reached"]

    accTitle: The byte pair encoding training loop
    accDescr: Count every adjacent pair in the training text, merge the single most frequent pair into one new token, then repeat using the updated text until the vocabulary reaches its target size.
</code></pre>

<p>Each merge adds exactly one new token to the vocabulary, so the number of merges run is a direct, chosen input to training — not something the algorithm discovers on its own.</p>

<p>Nothing in that loop requires a symbol to be a single original character. The most frequent pair at any step might be two individual characters, a character and an already-merged piece, or two already-merged pieces — the algorithm looks at whatever symbols currently exist and merges the most frequent adjacent pair among them, every time. That’s also why the name holds up past the first few merges: “pair” describes merging two adjacent symbols at a time, not a limit on how large either one already is. The paper itself merges well past single characters — it describes the result of a merge as “a new symbol which represents a character n-gram,” and says “frequent character n-grams (or whole words) are eventually merged into a single symbol,” all still under the same name.</p>

<h2 id="worked-example">Worked Example</h2>

<p>Starting vocabulary: individual letters. Training text (as characters): <code class="language-plaintext highlighter-rouge">l o w</code>, <code class="language-plaintext highlighter-rouge">l o w</code>, <code class="language-plaintext highlighter-rouge">l o w e r</code>, <code class="language-plaintext highlighter-rouge">n e w</code>, <code class="language-plaintext highlighter-rouge">n e w e r</code>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
</pre></td><td class="rouge-code"><pre>Step 1: most frequent adjacent pair is (l, o) -&gt; merge into "lo"
Step 2: most frequent remaining pair is (lo, w) -&gt; merge into "low"
Step 3: most frequent remaining pair is (n, e) -&gt; merge into "ne"
... repeat until the vocabulary reaches its target size
</pre></td></tr></tbody></table></code></pre></div></div>

<p>Common chunks like <code class="language-plaintext highlighter-rouge">low</code> become single tokens quickly. Rare combinations stay split into smaller pieces — an unseen word gets spelled out of the pieces the model does have, character by character if it has to.</p>

<h2 id="applying-it-to-new-text">Applying It to New Text</h2>

<p>The merges learned during training don’t just build the vocabulary — they double as the rulebook a tokenizer applies to brand-new text (<a href="/posts/tokens-not-words/">Part 3</a>), in the exact order they were learned:</p>

<pre><code class="language-mermaid">flowchart LR
    W["new word, split&lt;br/&gt;into individual characters"] --&gt; M["apply the learned&lt;br/&gt;merges, in the order&lt;br/&gt;they were learned"]
    M --&gt; T["a sequence of&lt;br/&gt;vocabulary tokens"]

    accTitle: Applying learned BPE merges to new text
    accDescr: A new word is split into individual characters, the learned merges are applied in the order they were learned, and the result is a sequence of vocabulary tokens.
</code></pre>

<p>A word the algorithm merged early and often, like <code class="language-plaintext highlighter-rouge">low</code>, collapses into one token almost immediately. A word that shares none of its structure with anything in the training text never matches an available merge, and stays split into individual characters — exactly the worst-case, one-piece-at-a-time behavior <a href="/posts/tokens-not-words/">Part 3</a> described for unrecognized input, without ever falling back to a generic “unknown” token.</p>

<h2 id="why-this-paper-matters">Why This Paper Matters</h2>

<p>This is the algorithm behind the vocabularies described in <a href="/posts/tokens-not-words/">Part 3</a>. GPT-2’s entire 50,257-token vocabulary, for example, is built exactly this way, <a href="https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf">by its own paper’s account</a>: 256 starting bytes (a byte-level variant of the character-level version above), 50,000 learned merges, plus one special end-of-sequence token — a real, count-for-count example of the training loop above, running at production scale.</p>

<p>It’s also the actual mechanism behind two things <a href="/posts/tokens-not-words/">Part 3</a> only stated as facts: why a rare word costs more tokens than a common one, and why non-English text often costs more too. A piece only becomes its own single token if it was frequent enough in the training data to earn a merge. Rare words, and words from languages the training data had less of, earn fewer merges, so they stay split into more, smaller pieces — while common words and phrases, trained on far more data, collapse into single tokens almost immediately.</p>

<hr />
<p><em>Next: <a href="/posts/embeddings/">Embeddings</a> — how a token becomes a vector in the embedding table.</em></p>]]></content><author><name></name></author><category term="AI" /><category term="AI" /><category term="LLM" /><category term="Machine Learning" /><category term="Tokenization" /><summary type="html"><![CDATA[A model with a fixed vocabulary (Part 3) can't handle a word it has never seen — a made-up word, a rare name, a typo.]]></summary></entry><entry><title type="html">Tokens, Not Words — LLMs Part 3</title><link href="https://sachinjoseph.com/posts/tokens-not-words/" rel="alternate" type="text/html" title="Tokens, Not Words — LLMs Part 3" /><published>2026-09-30T10:16:20+00:00</published><updated>2026-10-02T06:20:37+00:00</updated><id>https://sachinjoseph.com/posts/tokens-not-words</id><content type="html" xml:base="https://sachinjoseph.com/posts/tokens-not-words/"><![CDATA[<h2 id="the-definition">The Definition</h2>

<p>A <strong>token</strong> is the actual unit a language model reads and predicts. It is not always a word. It can be a whole word, part of a word, or a single punctuation mark.</p>

<p>Before a model is trained, its builders fix a list of allowed tokens, called a <strong>vocabulary</strong>. Every model has its own vocabulary, typically tens of thousands of entries. A <strong>tokenizer</strong> is the program that splits any input text into tokens from that vocabulary — a fixed procedure, decided once before training, that never changes once the model is in use.</p>

<h2 id="why-subword-not-whole-words">Why Subword, Not Whole Words</h2>

<p>A vocabulary of whole words alone can’t handle a word it has never seen before — a typo, a made-up name, a rare technical term; there’s simply no entry for it. A vocabulary of individual characters could handle anything, but at a real cost: a word like “unhappiness” would need 11 separate tokens, one per letter, instead of a handful of larger pieces. Subword tokenization splits the difference: common words stay whole, and rare or unfamiliar ones break into smaller, reusable pieces — “unhappiness” becomes 3 tokens, not 11 or 1, shown below.</p>

<h2 id="vocabulary-size-varies-by-domain">Vocabulary Size Varies by Domain</h2>

<p>“Tens of thousands of entries,” from the top of this post, covers a real range. English-focused models tend toward the smaller end — Llama 2 uses about 32,000 tokens, Falcon about 65,000, and OpenAI’s Generative Pre-trained Transformer (GPT) line started at about 50,000 with GPT-2. Models built to handle many languages well need far more: GPT-4’s tokenizer uses about 100,000, Llama 3 about 128,000, and heavily multilingual models like mT5 and BLOOM (BigScience Large Open-science Open-access Multilingual Language Model) go up to around 250,000. Roughly, a multilingual vocabulary needs 2 to 3 times as many entries as an English-only one to avoid the same over-fragmentation problem non-English text already has in a smaller vocabulary.</p>

<p>Code doesn’t really need a <em>bigger</em> vocabulary — it needs the right entries allocated differently. Whitespace and indentation make up a large share of any code file, but are rare enough in ordinary English prose that a tokenizer built only for English gives them almost no dedicated tokens. Point that same tokenizer at Python and every level of indentation costs several tokens just to represent blank space. A tokenizer meant to handle code well, like GPT-4’s, deliberately adds tokens for common runs of whitespace, so indentation costs close to one token instead of many.</p>

<p>Highly specialized domains — biomedical research, law, physics and math — run into a similar problem from a different angle: a general-purpose vocabulary was never built from enough of that domain’s own text, so its distinctive terms fragment into meaningless pieces, the same way an unusually long or unfamiliar word does. A drug name, a legal doctrine, or a block of mathematical notation can all end up split into pieces that don’t line up with any meaningful unit in the field. Models built for these domains often use their own custom vocabulary instead, trained on that domain’s own text — a biomedical model called SciBERT, for instance, uses a 30,000-token vocabulary built specifically from a mix of scientific and biomedical papers, and specialized legal models have used custom vocabularies of a similar size built from legal text.</p>

<p>One more distinction worth being precise about: a search engine’s “tokenization” is not this at all. It’s a much simpler, older idea — splitting text into words for a search index, usually by whitespace and punctuation, sometimes reduced further so different forms of a word match each other. It shares the word “tokenization” with what this post describes, but not the mechanism, and not the goal.</p>

<h2 id="how-a-tokenizer-splits-text">How a Tokenizer Splits Text</h2>

<p>Given text, a tokenizer’s job is to turn it into a sequence of tokens from its fixed vocabulary:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Tokenization step
    accDescr: Text goes into the tokenizer and a sequence of vocabulary tokens comes out.
    TXT["text"] --&gt;|tokenizer| TOK["tokens"]
</code></pre>

<p>A tokenizer can only ever produce tokens that are already in its vocabulary — it has no way to invent a new one on the spot, even for text it’s never seen before. Common short words usually become one token each. Longer or rarer words often split into pieces — roughly like this, for illustration (the exact split varies by tokenizer):</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
</pre></td><td class="rouge-code"><pre>"the"            -&gt; [the]
"cats"           -&gt; [cat, s]
"unhappiness"    -&gt; [un, happi, ness]
"antidisestablishmentarianism" -&gt; [anti, dis, establish, ment, arian, ism]
</pre></td></tr></tbody></table></code></pre></div></div>

<p>The exact split depends on the tokenizer’s vocabulary — different models split the same word differently. A future post covers the actual algorithm most tokenizers use to build that vocabulary.</p>

<p>A vocabulary is fixed before training and never grows afterward, so what happens when the input has something outside it — an emoji, an unfamiliar writing system, a garbled string of characters? Older tokenizers replaced anything they didn’t recognize with a single generic “unknown” token, throwing that piece of text away entirely. Modern tokenizers avoid this: their vocabulary also includes every individual raw byte, so any input can always be represented, worst case one byte at a time. Nothing is ever truly unrecognizable — text with no matching pieces in the vocabulary just costs far more tokens to represent, one byte at a time instead of one word or subword at a time.</p>

<p>The tokenizer isn’t part of the neural network itself. It runs once, as a fixed step before any of the math in the network’s layers happens: text goes in, a list of integers comes out, and only then does the network — through the vocabulary lookup a future post covers — actually begin its calculations.</p>

<h2 id="from-tokens-to-numbers-and-back">From Tokens to Numbers, and Back</h2>

<p>Once split, the tokenizer replaces each token with a number called its <strong>token ID</strong> — its position in the vocabulary list. The network never sees the text “cat”; it sees a token ID, like <code class="language-plaintext highlighter-rouge">4187</code>. Every distinct token has exactly one such number, and the same token always gets the same number: the mapping is fixed once the vocabulary is built, not reassigned from run to run. That number is arbitrary, though — token 4187 isn’t “closer” to token 4188 than it is to token 90210, any more than “cat” being word #4187 in a dictionary would make it related to word #4188. Fixed and unique, but still meaningless: the integer only distinguishes one token from another; it carries no meaning by itself. That’s exactly why a further step is needed before the network can do anything useful with it:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Tokens to integers
    accDescr: Each token is replaced by its numeric position in the fixed vocabulary list.
    TOK["tokens"] --&gt;|"position in&lt;br/&gt;vocabulary"| NUM["integers"]
</code></pre>

<p>Generating text reverses this exactly: the model predicts a number, that number maps back to its token, and the token’s text gets appended to the output. This is the mechanism behind the step <a href="/posts/what-is-a-language-model/">Part 1</a> described as picking a token and adding it to the text:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Generating text from integers
    accDescr: A predicted integer maps back to its token, whose text is appended to the output.
    NUM["integers"] --&gt;|"vocabulary&lt;br/&gt;lookup"| TOK["tokens"] --&gt;|"append"| TXT["text"]
</code></pre>

<h2 id="numbers-in-text-vs-token-ids">Numbers in Text vs. Token IDs</h2>

<p>“Number” means two unrelated things here, worth telling apart. A digit that appears <em>in the text</em> — like the “87439” in a prompt — is just text: the tokenizer splits it the same way it splits any other text, with no special awareness that it’s a number at all. It might become <code class="language-plaintext highlighter-rouge">["874", "39"]</code>, purely because those digit groupings happened to be common in the tokenizer’s training data — not because 874 and 39 mean anything mathematically. The <em>token ID</em> is a second, separate number: the vocabulary assigns each of those pieces its own arbitrary position, same as any other token, completely unrelated to the digits it spells out:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Digits versus token IDs
    accDescr: The text 87439 splits into tokens 874 and 39, which map to the unrelated vocabulary IDs 23891 and 118.
    N["text: 87439"] --&gt;|tokenizer| P["tokens: 874, 39"]
    P --&gt;|"vocabulary&lt;br/&gt;position"| I["ids: 23891, 118"]
</code></pre>

<p>Even a token whose text happens to look like a number follows the same rule: the token spelled <code class="language-plaintext highlighter-rouge">"874"</code> doesn’t get token ID 874, or anything close to it. Its ID is just whichever slot that string landed in when the vocabulary was built, with no connection at all to the digits it spells out — as arbitrary as any other token’s ID.</p>

<p>This causes a real, documented problem: because the split is based on training-data frequency, not place value, the same three-digit chunk can land in the hundreds place in one number and the units place in another — <code class="language-plaintext highlighter-rouge">"87439"</code> might split as <code class="language-plaintext highlighter-rouge">["874", "39"]</code> in one case and <code class="language-plaintext highlighter-rouge">["87", "439"]</code> in a different one. The model isn’t doing arithmetic on digits the way a calculator would; it’s predicting token sequences, and those tokens don’t line up with place value consistently. This is a real contributor to LLMs making arithmetic mistakes that would surprise a calculator.</p>

<h2 id="special-tokens">Special Tokens</h2>

<p>Not every entry in a vocabulary is a piece of ordinary text. A tokenizer’s vocabulary also includes a handful of <strong>special tokens</strong> that mark structure instead of content — most importantly, an <strong>end-of-sequence token</strong> that marks where the text stops. When the model predicts that token instead of an ordinary one, generation stops. That’s the actual mechanism behind <a href="/posts/what-is-a-language-model/">Part 1</a>’s “until the answer is done”: the model isn’t following some separate stopping rule, it’s just predicting one more token like any other, and that token happens to mean <em>stop</em>. Like any other token, how likely it is to come next is shaped entirely by training, not by a hard-coded rule — nothing stops it from being predicted mid-sentence except that training never gave it a reason to.</p>

<h2 id="putting-it-together">Putting It Together</h2>

<p><strong>Input tokens</strong> and <strong>output tokens</strong> aren’t two different kinds of thing — they’re positions in the exact same vocabulary, just moving in opposite directions. What the model reads and what it predicts share one fixed list; there’s no separate “output vocabulary.”</p>

<p>That makes generation one repeating loop:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: The full request-and-response loop
    accDescr: Text becomes integers, the network turns them into a new integer, and that integer becomes new text fed back as the next input until the end-of-sequence token appears.
    IN["your text"] --&gt; ENC["tokens -&gt; integers"]
    ENC --&gt; NET["the network"]
    NET --&gt; DEC["integers -&gt; tokens"]
    DEC --&gt; OUT["new text&lt;br/&gt;↻ appended, fed back&lt;br/&gt;in as the next input"]
</code></pre>

<p>Everything between “integers in” and “integers out” is the network itself: each integer becomes a list of numbers — an embedding, still a future post — and that list is exactly the x1…xn a <a href="/posts/what-a-neural-network-actually-is/">neural network layer</a> already defined. The same weights, bias, and nonlinear step from that post are what actually process every token passing through, all the way until a new integer comes out the other side. The tokenizer turns that integer back into a token and text, and the loop repeats — until the model predicts the end-of-sequence token described above, and generation stops.</p>

<h2 id="why-tokens-matter">Why Tokens Matter</h2>

<p>Everything measured about an LLM — how long a conversation it can hold and its input and output limits (both covered in a future post), and the price of a request (covered in a future post too) — is measured in tokens, not words or characters. A short, common word usually costs one token. A rare word or a typo often costs several, splitting into smaller pieces the same way the longer examples above did. Most non-English text costs more too, but for a different reason: the vocabulary was built mostly from one language’s text, so other languages’ ordinary, common words are under-represented in it — not because they’re unusual, just because there was less of them to learn from. The same sentence can end up costing noticeably more tokens in one language than another as a result.</p>

<p>Token counts can be surprising for another reason, too: a word’s leading space is often folded into its own token rather than costing a separate one — <code class="language-plaintext highlighter-rouge">" cat"</code> and <code class="language-plaintext highlighter-rouge">"cat"</code> are usually two different tokens in the vocabulary, not the same token plus a space. Where the spaces fall changes the count, not just which words appear.</p>

<p>Capitalization can do the same thing. Many tokenizers preserve case rather than ignoring it, so <code class="language-plaintext highlighter-rouge">"The"</code> and <code class="language-plaintext highlighter-rouge">"the"</code> are also usually two separate vocabulary entries, not one token that happens to look different. A sentence in Title Case or written in all-caps can end up costing more tokens than the identical words in lowercase, for the same underlying reason as the leading-space case: the vocabulary was built from exact character sequences, and a different case is a different sequence.</p>

<p>As a rough sense of scale, English text averages around 4 characters per token — a little under one token per word. That number moves a lot with the specifics above: more punctuation, more unusual capitalization, or more non-English text all push the token count up relative to the character count.</p>

<hr />
<p><em>Next: <a href="/posts/paper-byte-pair-encoding/">Paper: Byte Pair Encoding</a> — the algorithm behind most tokenizer vocabularies.</em></p>

<p><em>This post uses “embedding” loosely — covered in a future post.</em></p>]]></content><author><name></name></author><category term="AI" /><category term="AI" /><category term="LLM" /><category term="Machine Learning" /><category term="Tokenization" /><category term="Tokens" /><summary type="html"><![CDATA[A token is the actual unit a language model reads and predicts — not always a word, but a whole word, part of a word, or a single punctuation mark.]]></summary></entry><entry><title type="html">What a Neural Network Actually Is — LLMs Part 2</title><link href="https://sachinjoseph.com/posts/what-a-neural-network-actually-is/" rel="alternate" type="text/html" title="What a Neural Network Actually Is — LLMs Part 2" /><published>2026-09-29T05:38:38+00:00</published><updated>2026-09-29T05:38:38+00:00</updated><id>https://sachinjoseph.com/posts/what-a-neural-network-actually-is</id><content type="html" xml:base="https://sachinjoseph.com/posts/what-a-neural-network-actually-is/"><![CDATA[<h2 id="the-definition">The Definition</h2>

<p>A <strong>neural network</strong> is a function: it takes in numbers and produces numbers out. Each number going in is called an <strong>input</strong> — nothing more than a plain number. A network might take two inputs, or thousands.</p>

<p>Its name is a loose analogy to brain cells, but the math underneath is ordinary multiplication and addition, with one <strong>twist</strong>. That twist is what makes a network more than a calculator, and it gets its own section below.</p>

<p>The network itself is built from smaller steps called <strong>layers</strong>. Each layer turns one set of numbers into a different set, and one layer’s output becomes the next layer’s input:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Layers chained into a network
    accDescr: Numbers flow left to right through layer 1, layer 2, any number of middle layers, and layer N; each layer's output is the next layer's input.
    IN["numbers in"] --&gt; L1["layer 1"] --&gt; L2["layer 2"] --- DOTS["⋯"] --&gt; LN["layer N"] --&gt; OUT["numbers out"]

    style DOTS fill:transparent,stroke:none
    style IN fill:transparent,stroke:none
    style OUT fill:transparent,stroke:none
</code></pre>

<h2 id="what-a-layer-is-made-of">What a Layer Is Made Of</h2>

<p>A layer is made of <strong>neurons</strong> — its basic units. This post covers the most common kind, a <em>fully connected</em> layer: each neuron looks at <em>every</em> number the layer receives, and produces exactly one number in return, so a layer’s neuron count sets its output count regardless of how many numbers came in.</p>

<p>Scale makes this concrete: a layer with 1,000 inputs and 100 neurons does <em>not</em> split those 1,000 numbers across the neurons. Every neuron sees all 1,000 of them, so connecting them takes 1,000 × 100 = 100,000 weights — one weight per neuron per input.</p>

<p>Here’s a layer with n inputs and m neurons. All n inputs sit inside one box, and that box connects to every neuron:</p>

<pre><code class="language-mermaid">%%{init: {'flowchart': {'nodeSpacing': 15, 'rankSpacing': 50}}}%%
flowchart LR
    accTitle: One fully connected layer
    accDescr: All n inputs connect to every one of the m neurons, and each neuron produces one output number.
    INPUTS["inputs&lt;br/&gt;&lt;br/&gt;x1&lt;br/&gt;x2&lt;br/&gt;⋮&lt;br/&gt;xn"]

    INPUTS --&gt;|"all n inputs"| N1["neuron 1&lt;br/&gt;weights w1&lt;br/&gt;bias b1"]
    INPUTS --&gt;|"all n inputs"| N2["neuron 2&lt;br/&gt;weights w2&lt;br/&gt;bias b2"]
    INPUTS ~~~ DOTS["⋮"]
    INPUTS --&gt;|"all n inputs"| Nm["neuron m&lt;br/&gt;weights wm&lt;br/&gt;bias bm"]

    N1 --&gt; y1["y1"]
    N2 --&gt; y2["y2"]
    DOTS ~~~ yDots["⋮"]
    Nm --&gt; ym["ym"]

    style DOTS fill:transparent,stroke:none
    style yDots fill:transparent,stroke:none
</code></pre>

<p>Every arrow carries all n inputs — every neuron reads every one of them, identically. What differs is what each neuron does with them: its own weights, labeled w1, w2, and so on inside its box, alongside its own bias. Neuron 2’s weights are never shared with neuron 1’s, even though both read all n inputs. Across all m neurons, that’s n × m weights in total, plus one bias per neuron (m more).</p>

<p>For a network’s first layer specifically, x1 through xn is one token’s embedding — covered in a future post.</p>

<p>Two adjustable numbers make up each neuron’s share of that count. A <strong>weight</strong> is one adjustable number per input, multiplied against its matching input — so a neuron’s weight count always equals its input count, no more, no fewer, and that count is fixed once the network is built. A <strong>bias</strong> is one more adjustable number, unique to that neuron, added in <em>after</em> the weights are multiplied. Multiply, then add the bias — that’s as far as plain arithmetic gets you, which is exactly where the twist comes in.</p>

<h2 id="what-a-neuron-is-made-of">What a Neuron Is Made Of</h2>

<p>A neuron is made of its weights and bias, covered above, plus one more piece. <strong>So, what’s the twist?</strong> After multiplying and adding, a neuron applies a <strong>nonlinear step</strong>: a fixed rule applied to a single number. A common one, called <strong><a href="https://en.wikipedia.org/wiki/Rectified_linear_unit">ReLU</a></strong> (Rectified Linear Unit), keeps the number if it’s positive and otherwise uses zero. Real LLMs often use smoother variants, such as <a href="https://arxiv.org/abs/1606.08415">GELU</a> (Gaussian Error Linear Unit), but the job is the same.</p>

<p>Weights and bias are the two per-neuron pieces from the previous section — every neuron has its own. The nonlinear step is different: it’s not a per-neuron adjustable number at all, just a fixed rule (like ReLU, defined above) applied the same way to every neuron in the layer. Training changes weights and biases; it doesn’t change which rule the nonlinear step uses.</p>

<p>This step earns the name “twist” because of what happens without it. Multiplying and adding alone can only ever produce a weighted sum — stack as many such layers as you like, and the whole network still collapses mathematically into one single weighted sum of the original inputs. The nonlinear step breaks that collapse, which is what lets stacked layers compute more than a single layer could.</p>

<p>Put the three pieces together, and a neuron does exactly three things in order: multiply each input by its weight, add up the results along with its bias, then apply the nonlinear step. That produces the neuron’s one output number. Collect every neuron’s output, and that’s the layer’s output. As a formula, neuron i’s output is:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
</pre></td><td class="rouge-code"><pre>yi = f( (x1 × wi1) + (x2 × wi2) + ... + (xn × win) + biasi )
</pre></td></tr></tbody></table></code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">wi1</code> is neuron i’s weight for input x1, <code class="language-plaintext highlighter-rouge">biasi</code> is neuron i’s bias, and <code class="language-plaintext highlighter-rouge">f</code> is the nonlinear step. i ranges from 1 to m — one such formula per neuron in the layer.</p>

<p>Together, all of a network’s weights and biases are called its <strong>parameters</strong>. An LLM with billions of parameters is a neural network with billions of these adjustable numbers. One identifiable chunk of that total comes directly from vocabulary size: turning each token into its embedding (a future post covers this) means storing one adjustable vector per vocabulary entry, so a bigger vocabulary means more of these stored vectors — before the rest of the network’s own layers add any parameters of their own.</p>

<p>Altogether, one neuron’s full path looks like this:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: What one neuron computes
    accDescr: Inputs are multiplied by weights and added with a bias, then a fixed nonlinear rule produces the single output.
    X["inputs&lt;br/&gt;x1 … xn"] --&gt;|"weights&lt;br/&gt;(unique to&lt;br/&gt;this neuron)"| SUM(["multiply &amp;amp; add,&lt;br/&gt;then + bias&lt;br/&gt;(unique to&lt;br/&gt;this neuron)"])
    SUM --&gt; F["nonlinear step&lt;br/&gt;(same fixed rule&lt;br/&gt;for every neuron&lt;br/&gt;in the layer)"]
    F --&gt; Y["y"]
</code></pre>

<h2 id="one-fixed-size-any-length-of-text">One Fixed Size, Any Length of Text</h2>

<p>A neuron’s fixed weight count raises a natural question: how does the same network handle a short prompt and a long document alike? Not by changing n. Text of any length is first broken into a sequence of same-size pieces, called tokens, and each token is turned into a fixed-size list of numbers, called an embedding, the same length every time — both covered in future posts. A layer’s neurons always take in one such fixed-size piece; what varies is how many pieces there are, not the size of any single one, and every piece runs through the same weights independently and at the same time, not one after another. Combining information across however many pieces are present is a separate mechanism, attention, also covered in a future post — not something this post’s layers do on their own.</p>

<h2 id="not-every-layer-is-fully-connected">Not Every Layer Is Fully Connected</h2>

<p>A fully connected layer isn’t the only design. A <strong>convolutional layer</strong> connects each neuron to only a small, local patch of its input, instead of the whole thing, and reuses that same small set of weights across every patch — well suited to images, where nearby pixels matter more than far-apart ones. A <strong>recurrent layer</strong> processes one piece of a sequence at a time, feeding its own previous output back in alongside the next piece — built for data where order matters, like reading text one word after another.</p>

<p>LLMs use neither of these to combine information across a sequence. They use attention instead (covered in a future post), which lets every position look directly at every other position at once — without a fixed local patch, and without processing one piece at a time in order.</p>

<h2 id="how-layers-chain-into-a-network">How Layers Chain Into a Network</h2>

<p>Layer 1’s outputs (y1 … ym) become layer 2’s inputs, and layer 2 works <em>exactly</em> the same way as layer 1 — same neuron mechanics, its own separate weights and biases:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Two layers chained
    accDescr: Layer 1 turns n network inputs into m outputs, which become layer 2's inputs for its k outputs; each layer keeps its own separate weights.
    X["network inputs&lt;br/&gt;x1 … xn"] --&gt;|"n weights&lt;br/&gt;per neuron"| L1["layer 1&lt;br/&gt;m neurons"]
    L1 --&gt;|"y1 … ym&lt;br/&gt;m weights&lt;br/&gt;per neuron"| L2["layer 2&lt;br/&gt;k neurons"]
    L2 --&gt; Z["outputs&lt;br/&gt;z1 … zk"]
</code></pre>

<p>Because layer 2 receives m numbers, each of its k neurons needs m weights of its own — one per incoming number, exactly like layer 1. Nothing is shared between layers; each has its own parameters. Layer N repeats this same pattern until the last layer’s output is the network’s final answer.</p>

<p>This is where the twist pays off: stacking layers with the nonlinear step lets a network <em>approximate very complex functions</em>. In theory, even one very wide layer could do this, but in practice stacking gets there far more efficiently.</p>

<p>None of this is useful yet, though — the network’s weights start out as random numbers. <strong>Training</strong> is the process of adjusting those weights until the network’s output gets closer to what you want. A future post covers training itself, and a later one works through its arithmetic by hand.</p>

<h2 id="worked-example">Worked Example</h2>

<p>Take one neuron with 2 inputs:</p>

<pre><code class="language-mermaid">flowchart LR
    accTitle: Worked neuron example
    accDescr: Inputs 0.8 and 0.6 times weights 0.7 and 0.5 plus bias minus 0.9 sum to minus 0.04, which the nonlinear step turns into 0.
    X1["x1 = 0.8"] --&gt;|"× w1 = 0.7"| SUM(["add up&lt;br/&gt;plus bias −0.9"])
    X2["x2 = 0.6"] --&gt;|"× w2 = 0.5"| SUM
    SUM --&gt;|"−0.04"| ACT["nonlinear step&lt;br/&gt;keep if positive, else 0"]
    ACT --&gt; OUT["output = 0"]
</code></pre>

<p>The same numbers, worked out:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
5
6
7
8
9
10
11
</pre></td><td class="rouge-code"><pre>x1 = 0.8,  w1 = 0.7
x2 = 0.6,  w2 = 0.5
bias = -0.9

sum = (x1 × w1) + (x2 × w2) + bias
    = (0.8 × 0.7) + (0.6 × 0.5) + (-0.9)
    =    0.56     +    0.30     +  -0.9
    = -0.04

nonlinear step (keep if positive, else 0):
    = 0
</pre></td></tr></tbody></table></code></pre></div></div>

<p>Change the inputs, keep the weights and bias fixed:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
5
6
</pre></td><td class="rouge-code"><pre>x1 = 0.9,  x2 = 0.9

sum = (0.9 × 0.7) + (0.9 × 0.5) + (-0.9) = 0.18

nonlinear step: 0.18 is positive, keep it
    = 0.18
</pre></td></tr></tbody></table></code></pre></div></div>

<p>Same weights, same bias, <em>different</em> inputs, different output. The weights and bias are what the network “knows” — they don’t change while the network is running, only during training. A neuron in a real LLM typically has thousands of inputs, not two.</p>

<h2 id="why-neural-networks-matter">Why Neural Networks Matter</h2>

<p>Every LLM is built from exactly this: layers of neurons, each multiplying its inputs by weights, adding a bias, then applying the nonlinear step. <a href="/posts/what-is-a-language-model/">Part 1</a>’s next-token predictor and the attention mechanism covered in a future post are both computed the same way underneath — numbers multiplied by adjustable weights, nothing more exotic than what this post covered.</p>

<hr />
<p><em>Next: <a href="/posts/tokens-not-words/">Tokens, Not Words</a> — how text becomes the numbers a network can use.</em></p>

<p><em>This post uses “training” and “token” loosely — both covered in future posts.</em></p>]]></content><author><name></name></author><category term="AI" /><category term="AI" /><category term="LLM" /><category term="Machine Learning" /><category term="Neural Networks" /><summary type="html"><![CDATA[A neural network is a function: it takes in numbers and produces numbers out, built from layers of neurons — weights, a bias, and one key nonlinear twist.]]></summary></entry><entry><title type="html">What Is a Language Model? — LLMs Part 1</title><link href="https://sachinjoseph.com/posts/what-is-a-language-model/" rel="alternate" type="text/html" title="What Is a Language Model? — LLMs Part 1" /><published>2026-09-28T01:48:14+00:00</published><updated>2026-10-02T06:20:37+00:00</updated><id>https://sachinjoseph.com/posts/what-is-a-language-model</id><content type="html" xml:base="https://sachinjoseph.com/posts/what-is-a-language-model/"><![CDATA[<h2 id="the-definition">The Definition</h2>

<p>A <strong>language model</strong> is a neural network trained to do one thing: given some text, predict what comes next. We’ll define a neural network in <a href="/posts/what-a-neural-network-actually-is/">Part 2</a>. For now, think of it as a program that learns from examples instead of being hand-coded.</p>

<p><strong>LLM</strong> is short for “large language model” — a language model built at a very large scale. Everything in this series is about that large-scale kind, since that’s what people mean by “LLM” today.</p>

<p>That’s the whole object. A next-word predictor, scaled up.</p>

<h2 id="the-idea">The Idea</h2>

<p>An LLM predicts text one small piece at a time. Each piece is called a <em>token</em>. We’ll define a token properly in a future post. For now, think of it as a word or part of a word.</p>

<p>To generate text, the model repeats one step: look at the text so far, predict the next token, add it to the text. Then repeat.</p>

<p>Writing, answering, and coding are all this same step, repeated many times.</p>

<h2 id="how-it-works-the-short-version">How It Works (the short version)</h2>

<ul>
  <li>You give it text: <code class="language-plaintext highlighter-rouge">"The capital of France is"</code></li>
  <li>It ranks every possible next token by probability: <code class="language-plaintext highlighter-rouge">Paris</code> (92%), <code class="language-plaintext highlighter-rouge">located</code> (3%), <code class="language-plaintext highlighter-rouge">a</code> (1%), …</li>
  <li>It picks one token and adds it to the text</li>
  <li>It repeats this, one token at a time, until the answer is done</li>
</ul>

<p>Even “done” is just another prediction: one entry in the model’s vocabulary is a special token that means <em>stop</em>, not an ordinary word, and the model predicts that token the same way it predicts any other. A future post covers this in more detail.</p>

<p>The model learned these probabilities during training. It read enormous amounts of text. Each time, it guessed the next word. Each time it guessed wrong, it adjusted itself slightly. It did this billions of times.</p>

<p>This explains <em>what</em> the model does. It doesn’t yet explain <em>how</em> it does it — that’s the rest of this series.</p>

<h2 id="example">Example</h2>

<p>Prompt: <code class="language-plaintext highlighter-rouge">"Roses are red, violets are"</code></p>

<p>The model’s next-token probabilities might look like this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
</pre></td><td class="rouge-code"><pre>blue    → 71%
violet  → 12%
purple  → 8%
loud    → 0.01%
</pre></td></tr></tbody></table></code></pre></div></div>

<p>It picks <code class="language-plaintext highlighter-rouge">blue</code>. Now it predicts the token after “blue.” Same process, one step later.</p>

<h2 id="why-language-models-matter">Why Language Models Matter</h2>

<p>An LLM is a next-token predictor. Nothing more, nothing hidden.</p>

<p>This explains a lot. It explains why an LLM can finish your sentence. It also explains why an LLM can confidently state something false. Both are the same action: predicting a plausible next token.</p>

<hr />
<p><em>Next: <a href="/posts/what-a-neural-network-actually-is/">What a Neural Network Actually Is</a> — layers, neurons, weights, and the one nonlinear twist that makes them more than a calculator.</em></p>

<p><em>This post uses several terms loosely: neural network, token, vocabulary, end-of-sequence token, training, “large.” Each gets a precise definition in a later part of the series.</em></p>]]></content><author><name></name></author><category term="AI" /><category term="AI" /><category term="LLM" /><category term="Machine Learning" /><summary type="html"><![CDATA[A language model is a neural network trained to do one thing: given some text, predict what comes next.]]></summary></entry><entry><title type="html">Configure PowerShell autocomplete using PSReadLine</title><link href="https://sachinjoseph.com/posts/configure-powershell-autocomplete-using-psreadline/" rel="alternate" type="text/html" title="Configure PowerShell autocomplete using PSReadLine" /><published>2022-11-27T12:55:40+00:00</published><updated>2026-10-01T05:39:06+00:00</updated><id>https://sachinjoseph.com/posts/configure-powershell-autocomplete-using-psreadline</id><content type="html" xml:base="https://sachinjoseph.com/posts/configure-powershell-autocomplete-using-psreadline/"><![CDATA[<p>Improving the PowerShell editing experience can greatly improve your productivity. <a href="https://learn.microsoft.com/en-us/powershell/module/psreadline/about/about_psreadline?view=powershell-7.3">PSReadLine</a>, in a line, is a PowerShell module that does just that - it provides improved syntax coloring, better multi-line editing, autocomplete, etc.</p>

<h3 id="install">INSTALL</h3>

<p>PowerShell ships with PSReadLine, but run the following command to install the latest version:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
</pre></td><td class="rouge-code"><pre><span class="n">Install-Module</span><span class="w"> </span><span class="nt">-Name</span><span class="w"> </span><span class="nx">PSReadLine</span><span class="w"> </span><span class="nt">-AllowClobber</span><span class="w"> </span><span class="nt">-Force</span><span class="w">
</span></pre></td></tr></tbody></table></code></pre></div></div>

<h3 id="configure">CONFIGURE</h3>

<p>PSReadLine can be configured using a profile. A PowerShell <a href="https://learn.microsoft.com/en-us/powershell/module/microsoft.powershell.core/about/about_profiles">profile</a> is a PowerShell script file that’s executed when a PowerShell starts.</p>

<h3 id="create-or-open-your-profile">Create (or open) your profile</h3>

<p>I recommend Visual Studio Code for almost all text editing, but any text editor (including notepad) would do:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
</pre></td><td class="rouge-code"><pre><span class="n">code</span><span class="w"> </span><span class="nv">$profile</span><span class="w">
</span></pre></td></tr></tbody></table></code></pre></div></div>

<h3 id="update-your-profile">Update your profile</h3>

<p>Add the following lines to your profile:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
2
3
4
5
</pre></td><td class="rouge-code"><pre><span class="n">Set-PSReadlineKeyHandler</span><span class="w"> </span><span class="nt">-Key</span><span class="w"> </span><span class="nx">UpArrow</span><span class="w"> </span><span class="nt">-Function</span><span class="w"> </span><span class="nx">HistorySearchBackward</span><span class="w">
</span><span class="n">Set-PSReadlineKeyHandler</span><span class="w"> </span><span class="nt">-Key</span><span class="w"> </span><span class="nx">DownArrow</span><span class="w"> </span><span class="nt">-Function</span><span class="w"> </span><span class="nx">HistorySearchForward</span><span class="w">
</span><span class="n">Set-PSReadLineOption</span><span class="w"> </span><span class="nt">-PredictionSource</span><span class="w"> </span><span class="nx">HistoryAndPlugin</span><span class="w"> </span><span class="c"># enable predictions</span><span class="w">
</span><span class="n">Set-PSReadLineOption</span><span class="w"> </span><span class="nt">-HistoryNoDuplicates</span><span class="w"> </span><span class="c"># prevent duplicates</span><span class="w">
</span><span class="n">Set-PSReadlineKeyHandler</span><span class="w"> </span><span class="nt">-Key</span><span class="w"> </span><span class="nx">Tab</span><span class="w"> </span><span class="nt">-Function</span><span class="w"> </span><span class="nx">MenuComplete</span><span class="w"> </span><span class="c"># provide a menu of completions when tab key is pressed</span><span class="w">
</span></pre></td></tr></tbody></table></code></pre></div></div>

<p>That’s it. Now, relaunch your profile to enjoy a much better PowerShell experience:</p>

<p><img src="/assets/images/posts/powershell-autocomplete.gif" alt="PowerShell autocomplete" /></p>

<p>Reference:</p>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/powershell/module/psreadline/about/about_psreadline?view=powershell-7.3">PSReadLine</a></li>
  <li><a href="https://learn.microsoft.com/en-us/powershell/module/psreadline/about/about_psreadline_functions?view=powershell-7.3">PSReadLine Functions</a></li>
  <li><a href="https://learn.microsoft.com/en-us/powershell/module/psreadline/set-psreadlineoption?view=powershell-7.3">Set-PSReadLineOption</a></li>
  <li><a href="https://learn.microsoft.com/en-us/powershell/module/psreadline/set-psreadlinekeyhandler?view=powershell-7.3">Set-PSReadLineKeyHandler</a></li>
</ul>]]></content><author><name></name></author><category term="Developer" /><category term="Windows Developer" /><category term="PowerShell" /><category term="PSReadLine" /><category term="pwsh" /><summary type="html"><![CDATA[Improving the PowerShell editing experience can greatly improve your productivity. PSReadLine, in a line, is a PowerShell module that does just that - it provides improved syntax coloring, better multi-line editing, autocomplete, etc.]]></summary></entry><entry><title type="html">Search Open Browser Tabs</title><link href="https://sachinjoseph.com/posts/search-open-browser-tabs/" rel="alternate" type="text/html" title="Search Open Browser Tabs" /><published>2022-11-23T14:33:24+00:00</published><updated>2026-10-01T05:39:06+00:00</updated><id>https://sachinjoseph.com/posts/search-open-browser-tabs</id><content type="html" xml:base="https://sachinjoseph.com/posts/search-open-browser-tabs/"><![CDATA[<h2 id="tldr">TL;DR:</h2>

<ul>
  <li>On Chromium-based browsers like <strong>Edge</strong> and <strong>Chrome</strong>, <strong>press Ctrl+Shift+A</strong>.</li>
  <li>On <strong>Firefox</strong>, press <strong>Ctrl+L</strong> (or Alt+D) to focus on the address bar, then <strong>type %</strong> and then <strong>tap the Spacebar</strong>.</li>
</ul>

<p>I have a lot of browser tabs open all the time, sometimes going to a hundred or more, and it’s often not very easy to find the tab that I am looking for. Thankfully, modern browsers support searching your open (and recently closed) tabs, and have very handy shortcuts to open tab-search.</p>

<h2 id="chromium-based-browsers-like-edge-and-chrome">Chromium-based browsers like Edge and Chrome</h2>

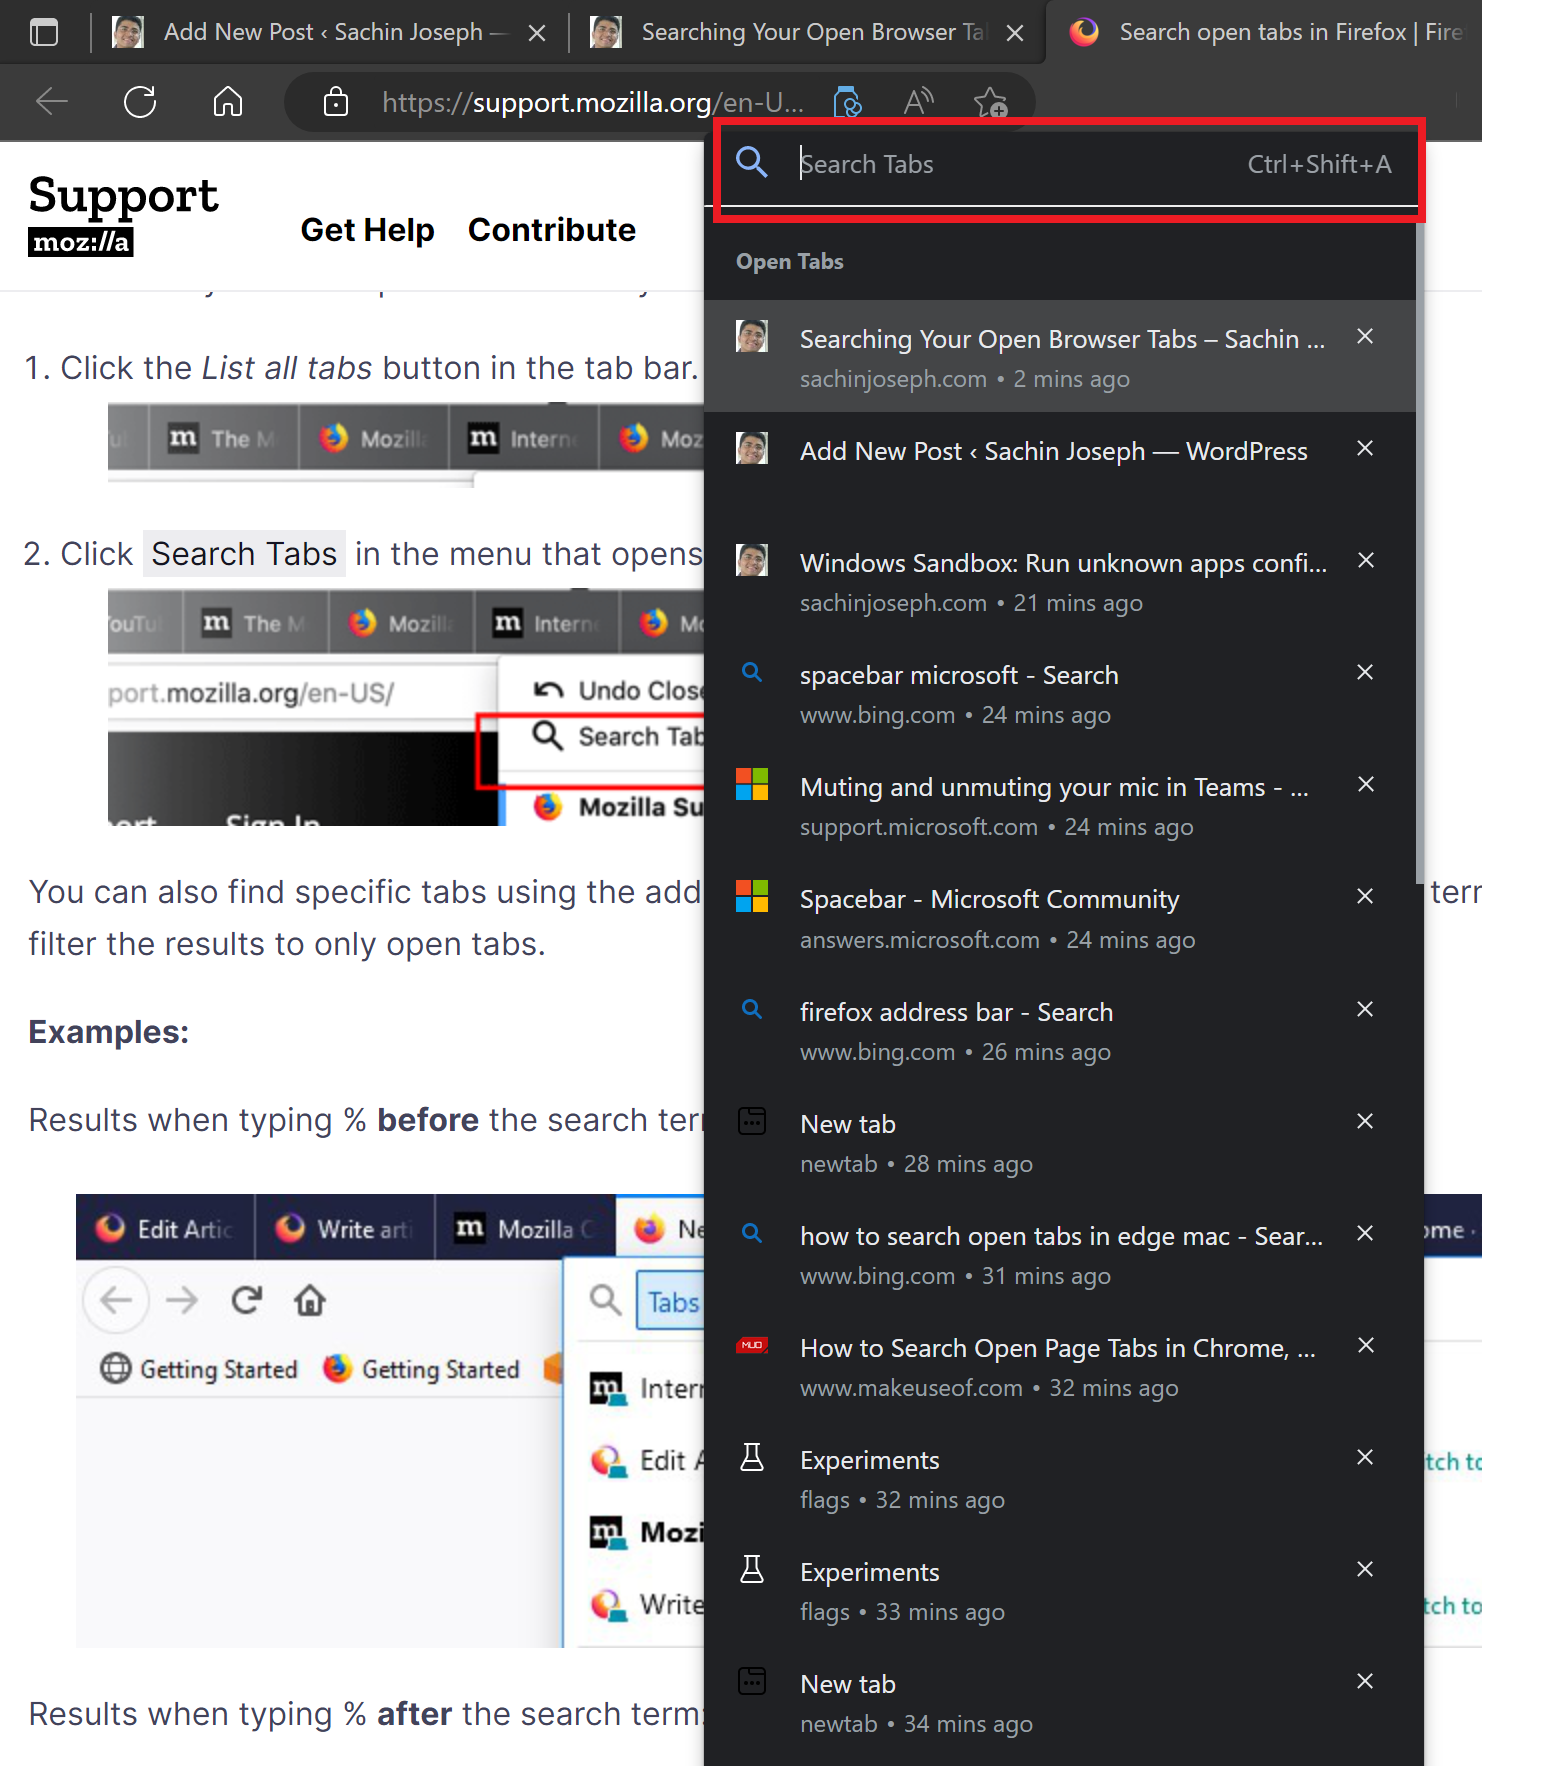
<p>Press <strong>Ctrl+Shift+A</strong> to open tab-search. See <a href="https://support.google.com/chrome/answer/2391819?hl=en&amp;co=GENIE.Platform=Desktop#zippy=%2Csearch-open-tabs-from-the-address-bar%2Csearch-open-tabs-with-tab-search">documentation</a>.</p>

<p><img src="/assets/images/posts/search-tabs-image-4.png" alt="Chrome tab search" /></p>

<h2 id="firefox">Firefox</h2>

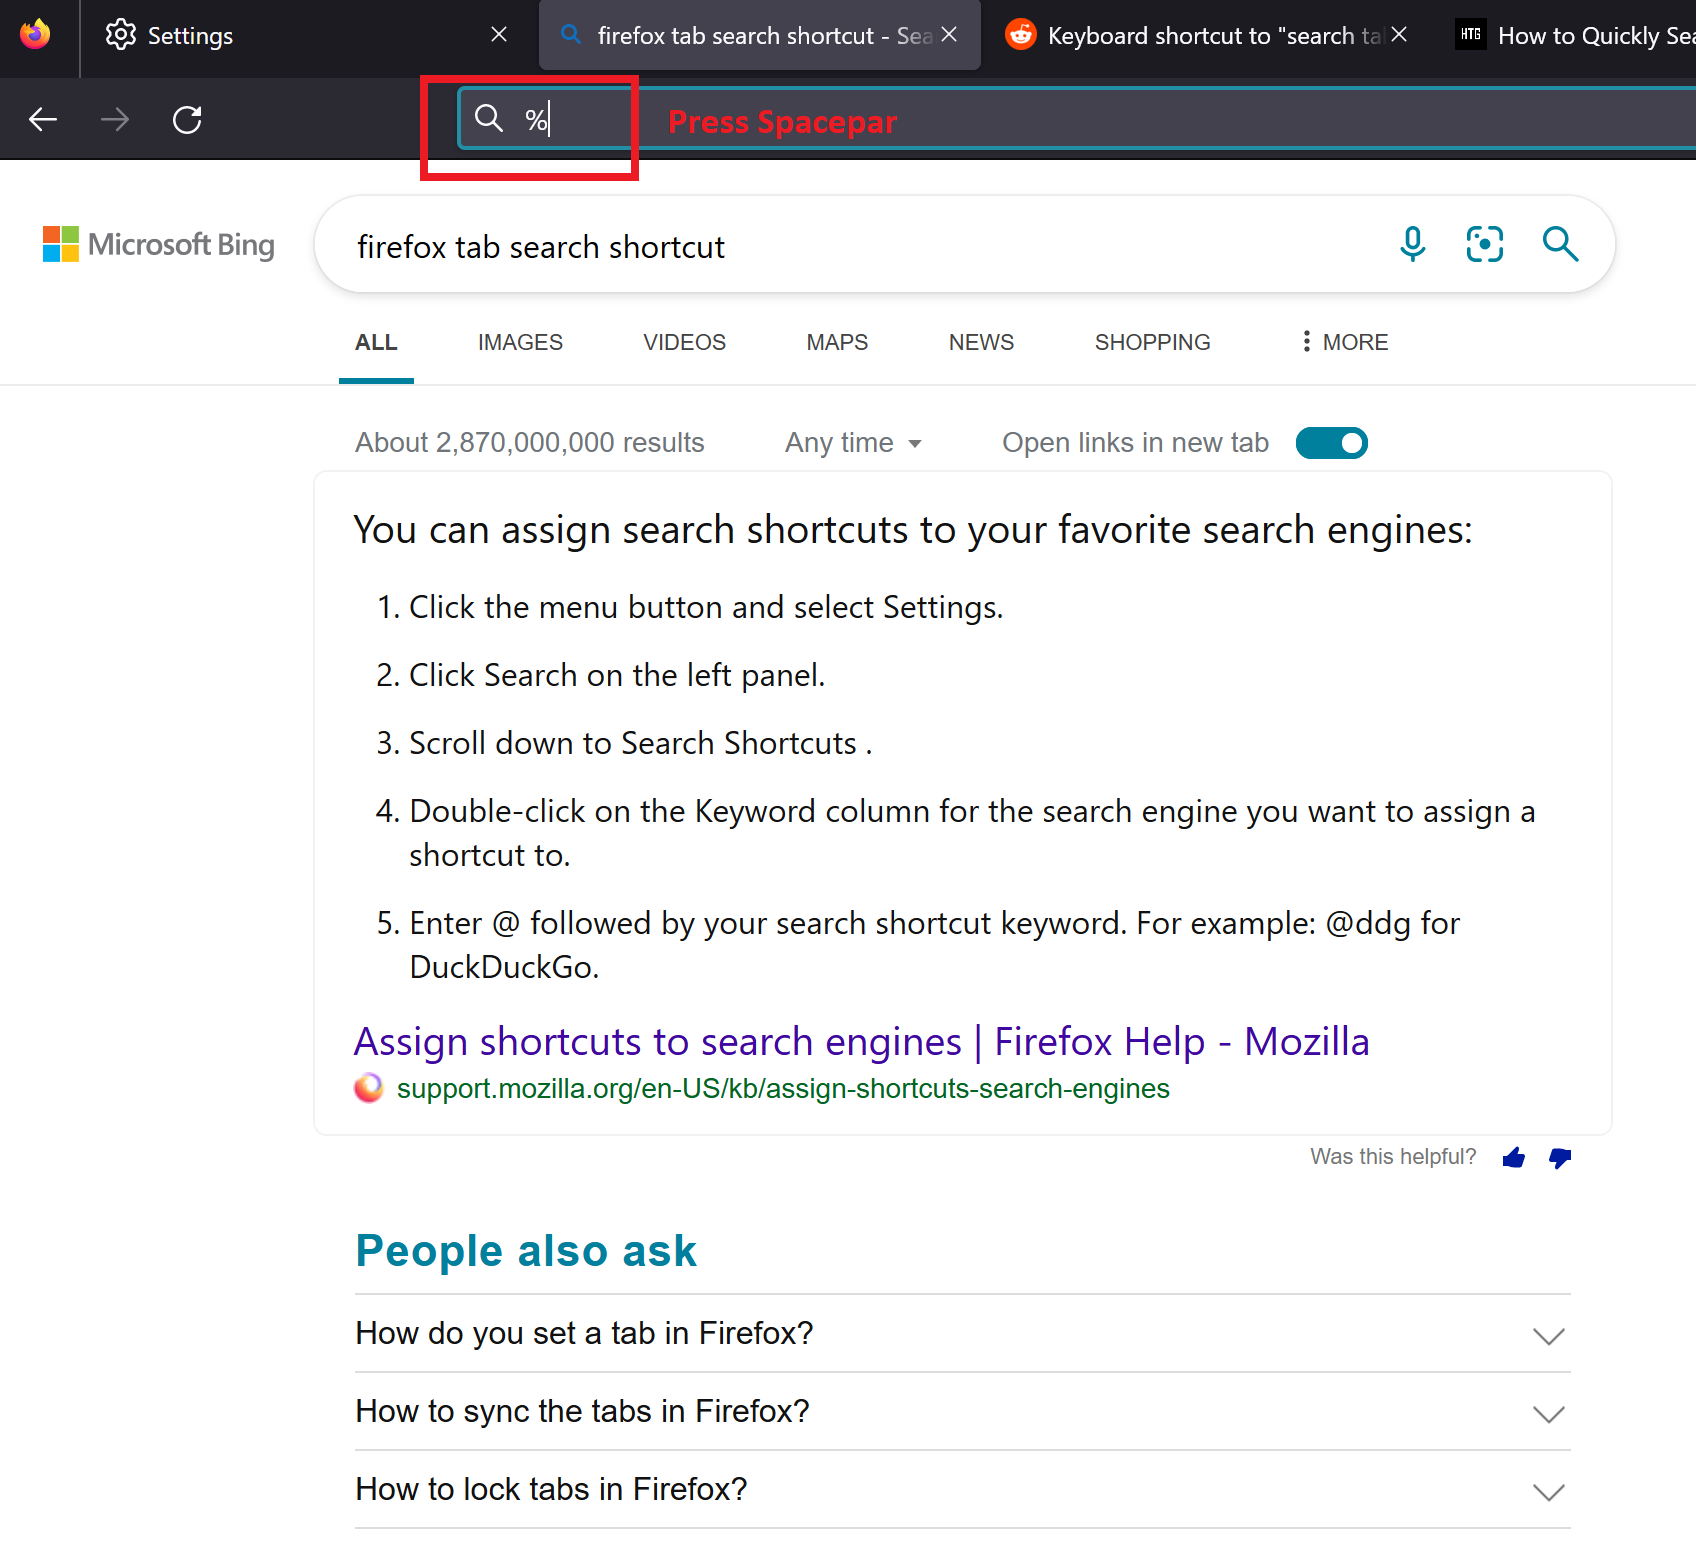
<p>Press <strong>Ctrl+L</strong> (or Alt+D) to focus on the address bar, then <strong>type %</strong> and then <strong>tap the Spacebar</strong> to search tabs. See <a href="https://support.mozilla.org/en-US/kb/search-open-tabs-firefox">documentation</a>.</p>

<p><img src="/assets/images/posts/search-tabs-image-2.png" alt="Firefox address bar" /></p>

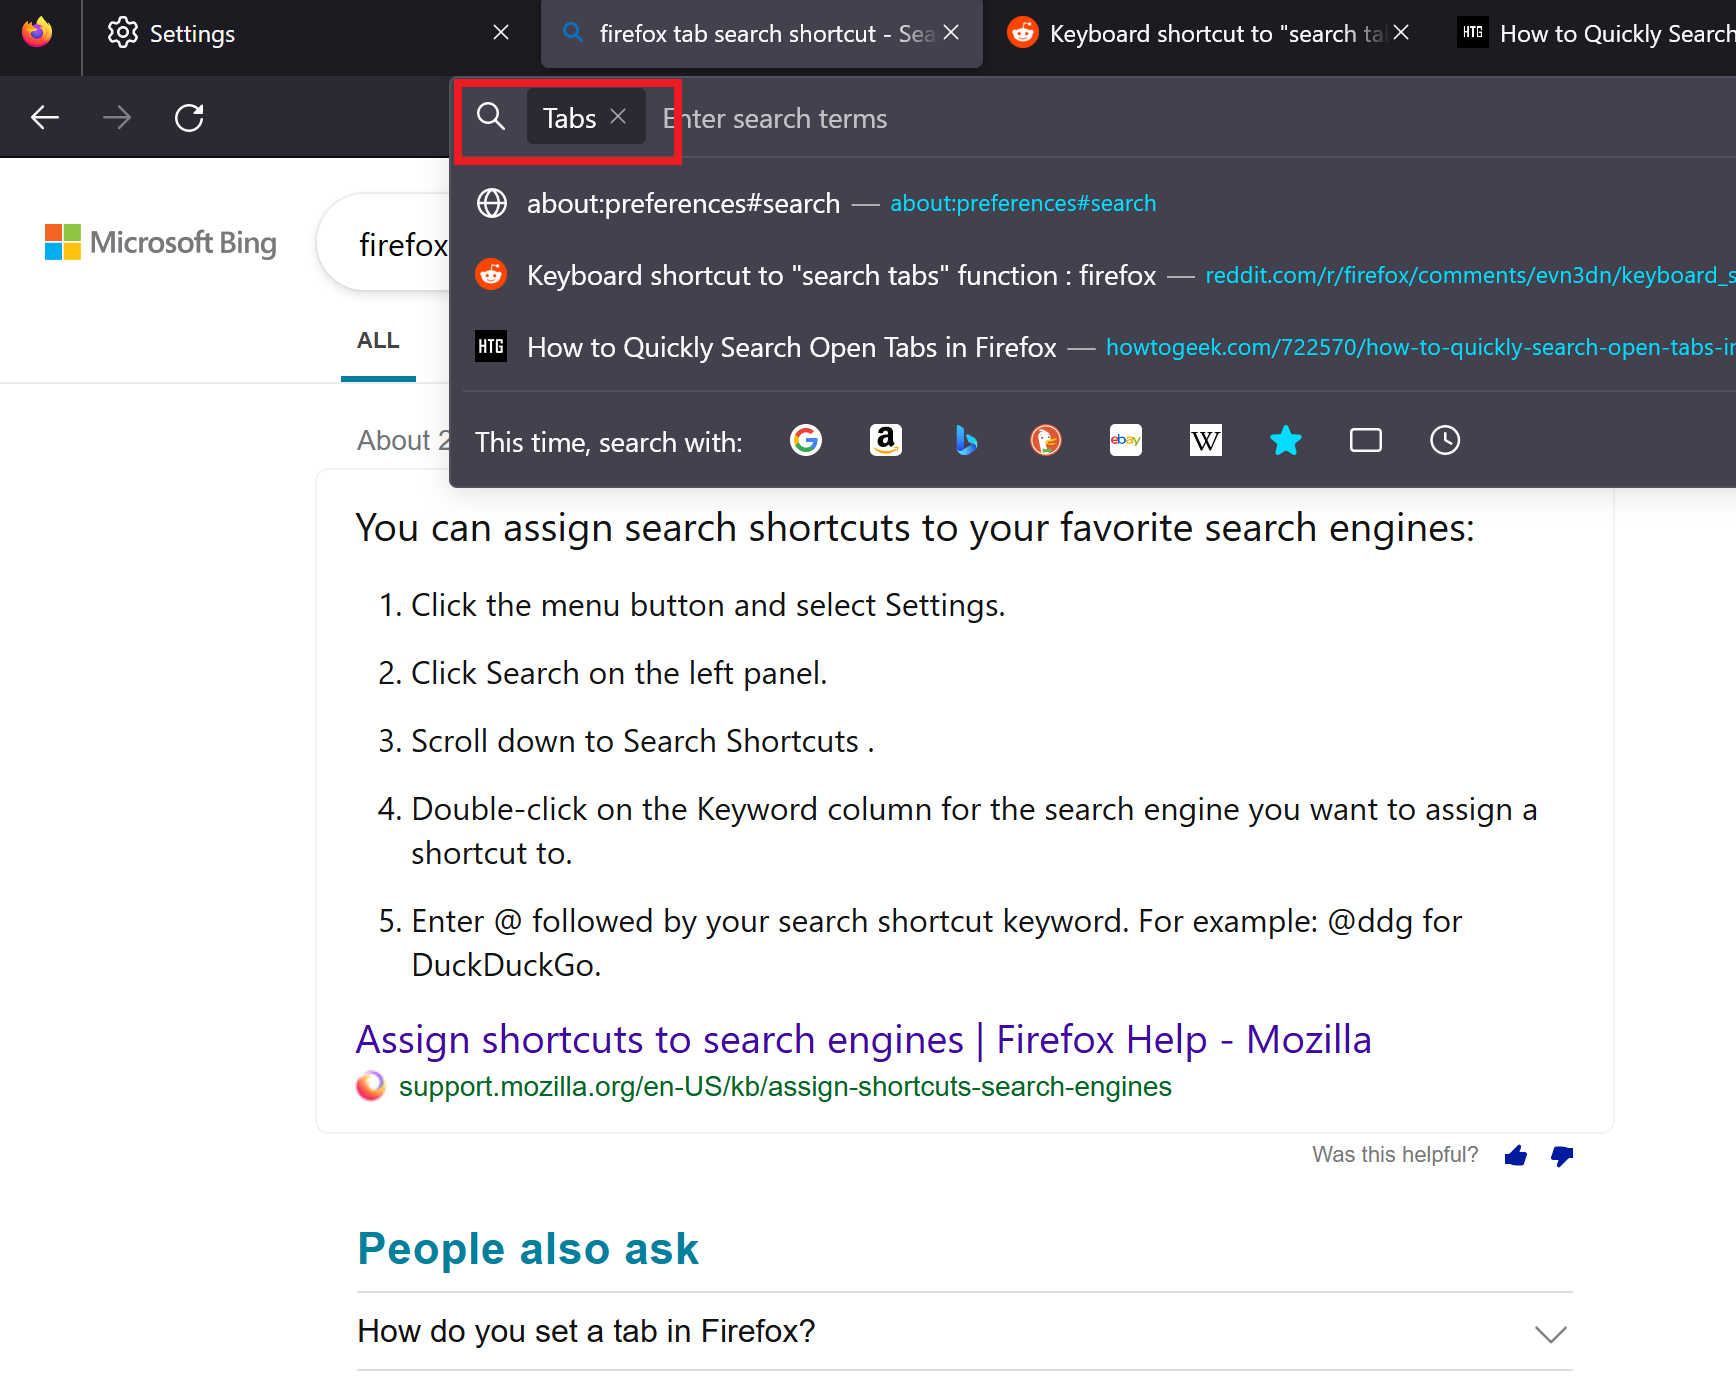
<p>That would switch the address bar to tab-search:</p>

<p><img src="/assets/images/posts/search-tabs-image-3.png" alt="Firefox tab search" /></p>

<p>Give it a try!</p>]]></content><author><name></name></author><category term="Developer" /><category term="Windows Developer" /><category term="Browser" /><category term="Chrome" /><category term="Chromium" /><category term="Edge" /><category term="Firefox" /><category term="Web" /><summary type="html"><![CDATA[On Chromium-based browsers like Edge and Chrome, press Ctrl+Shift+A. On Firefox, press Ctrl+L (or Alt+D), then type % and tap Spacebar.]]></summary></entry><entry><title type="html">Windows Sandbox: Run unknown apps confidently</title><link href="https://sachinjoseph.com/posts/windows-sandbox-run-unknown-apps-confidently/" rel="alternate" type="text/html" title="Windows Sandbox: Run unknown apps confidently" /><published>2020-04-25T13:56:14+00:00</published><updated>2026-10-01T05:39:06+00:00</updated><id>https://sachinjoseph.com/posts/windows-sandbox-run-unknown-apps-confidently</id><content type="html" xml:base="https://sachinjoseph.com/posts/windows-sandbox-run-unknown-apps-confidently/"><![CDATA[<p>Running unknown apps is <a href="https://stackoverflow.com/a/27014081/1724702">risky</a>:</p>

<ul>
  <li>Not immediately obvious what a program does.</li>
  <li>Unintended side effects (change the file system, send emails, etc.)</li>
  <li>Resource intensive, slow startup, blocking I/O, …</li>
</ul>

<p>But if you are like me, you frequently try downloading and running a lot of stuff you see on the internet. How do you run these apps safely? Of course, I can set up and maintain VMs for this, but it turns out there’s a much easier way: <a href="https://docs.microsoft.com/en-us/windows/security/threat-protection/windows-sandbox/windows-sandbox-overview">Windows Sandbox</a>.</p>

<p><img src="/assets/images/posts/windows-sandbox-image-1.png" alt="Windows Sandbox" /></p>

<p>According to the official documentation, Windows Sandbox provides a lightweight desktop environment to safely run applications in isolation. Any apps installs, files creates or modified, settings changes do not affect the host machine - all such changes are automatically undone the moment you close the Windows Sandbox. Effectively, it’s a VM maintained by Windows but you can’t have the VM-state saved.</p>

<h3 id="setting-up-the-windows-sandbox">Setting up the Windows Sandbox</h3>

<p>Windows Sandbox requires hardware virtualization and Windows 10 Pro or Enterprise build 18305 or newer. Turn on virtualization in BIOS, or if you are on a VM, then enable nested virtualization using PowerShell:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><table class="rouge-table"><tbody><tr><td class="rouge-gutter gl"><pre class="lineno">1
</pre></td><td class="rouge-code"><pre><span class="n">Set</span><span class="w"> </span><span class="nt">-VMProcessor</span><span class="w"> </span><span class="nt">-VMName</span><span class="w"> </span><span class="err">&lt;</span><span class="nx">VMName</span><span class="err">&gt;</span><span class="w"> </span><span class="nt">-ExposeVirtualizationExtensions</span><span class="w"> </span><span class="bp">$true</span><span class="w">
</span></pre></td></tr></tbody></table></code></pre></div></div>

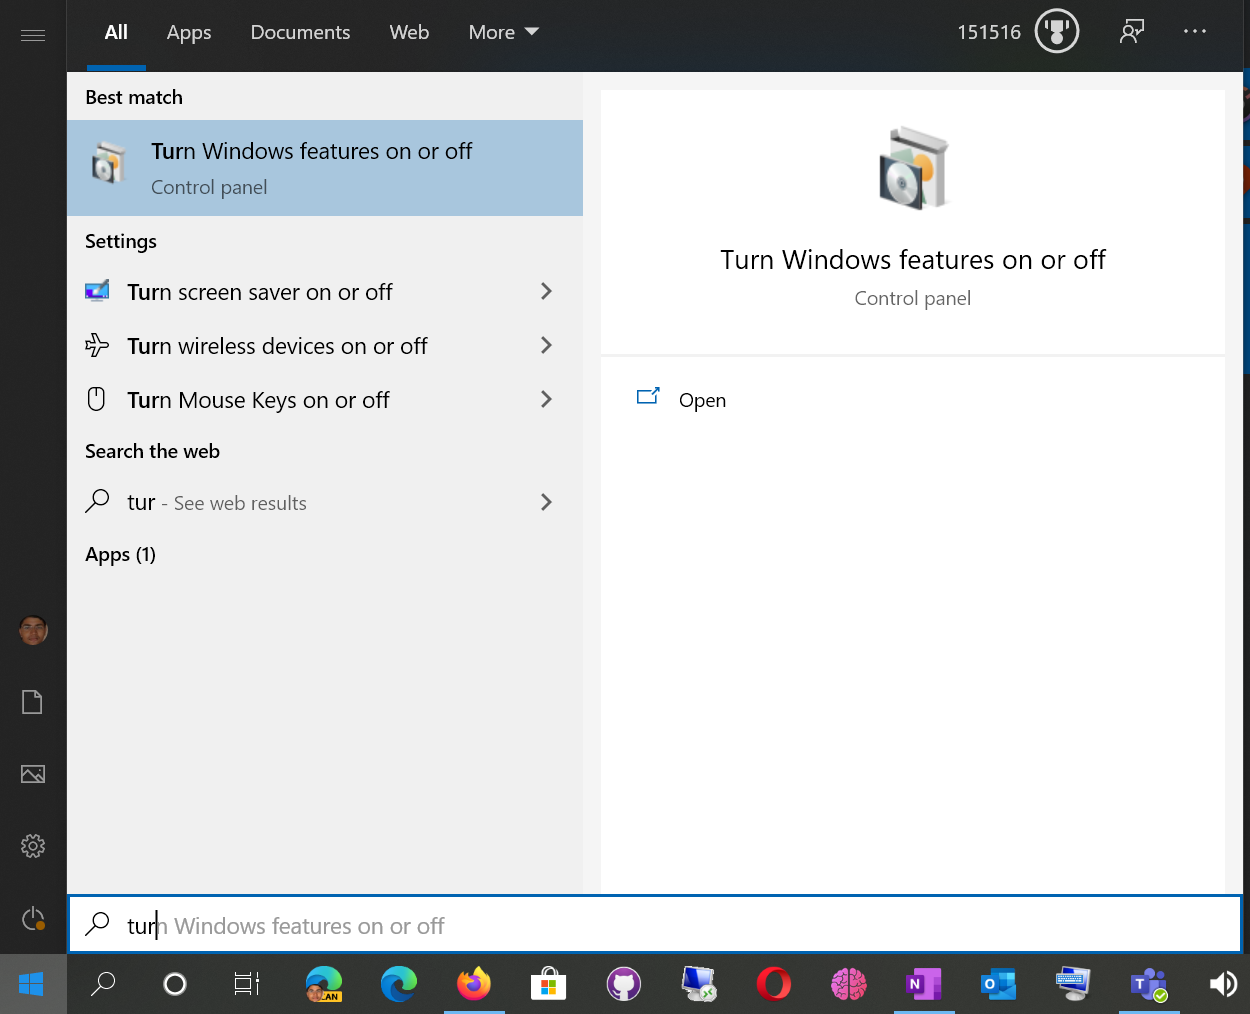
<p>Now, open Windows Features by typing ‘Turn Windows features on or off” in Start:</p>

<p><img src="/assets/images/posts/windows-sandbox-image-3.png" alt="Turn Windows features on or off" /></p>

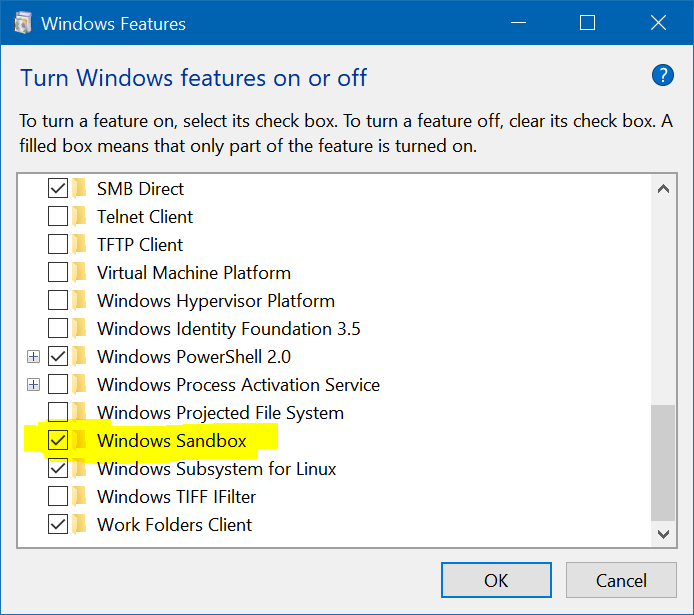
<p>Enable Windows Sandbox:</p>

<p><img src="/assets/images/posts/windows-sandbox-image-4.png" alt="Enable Windows Sandbox" /></p>

<p>That’s it. Your Windows Sandbox is set up and ready.</p>

<h3 id="testing-an-app-in-the-windows-sandbox">Testing an app in the Windows Sandbox</h3>

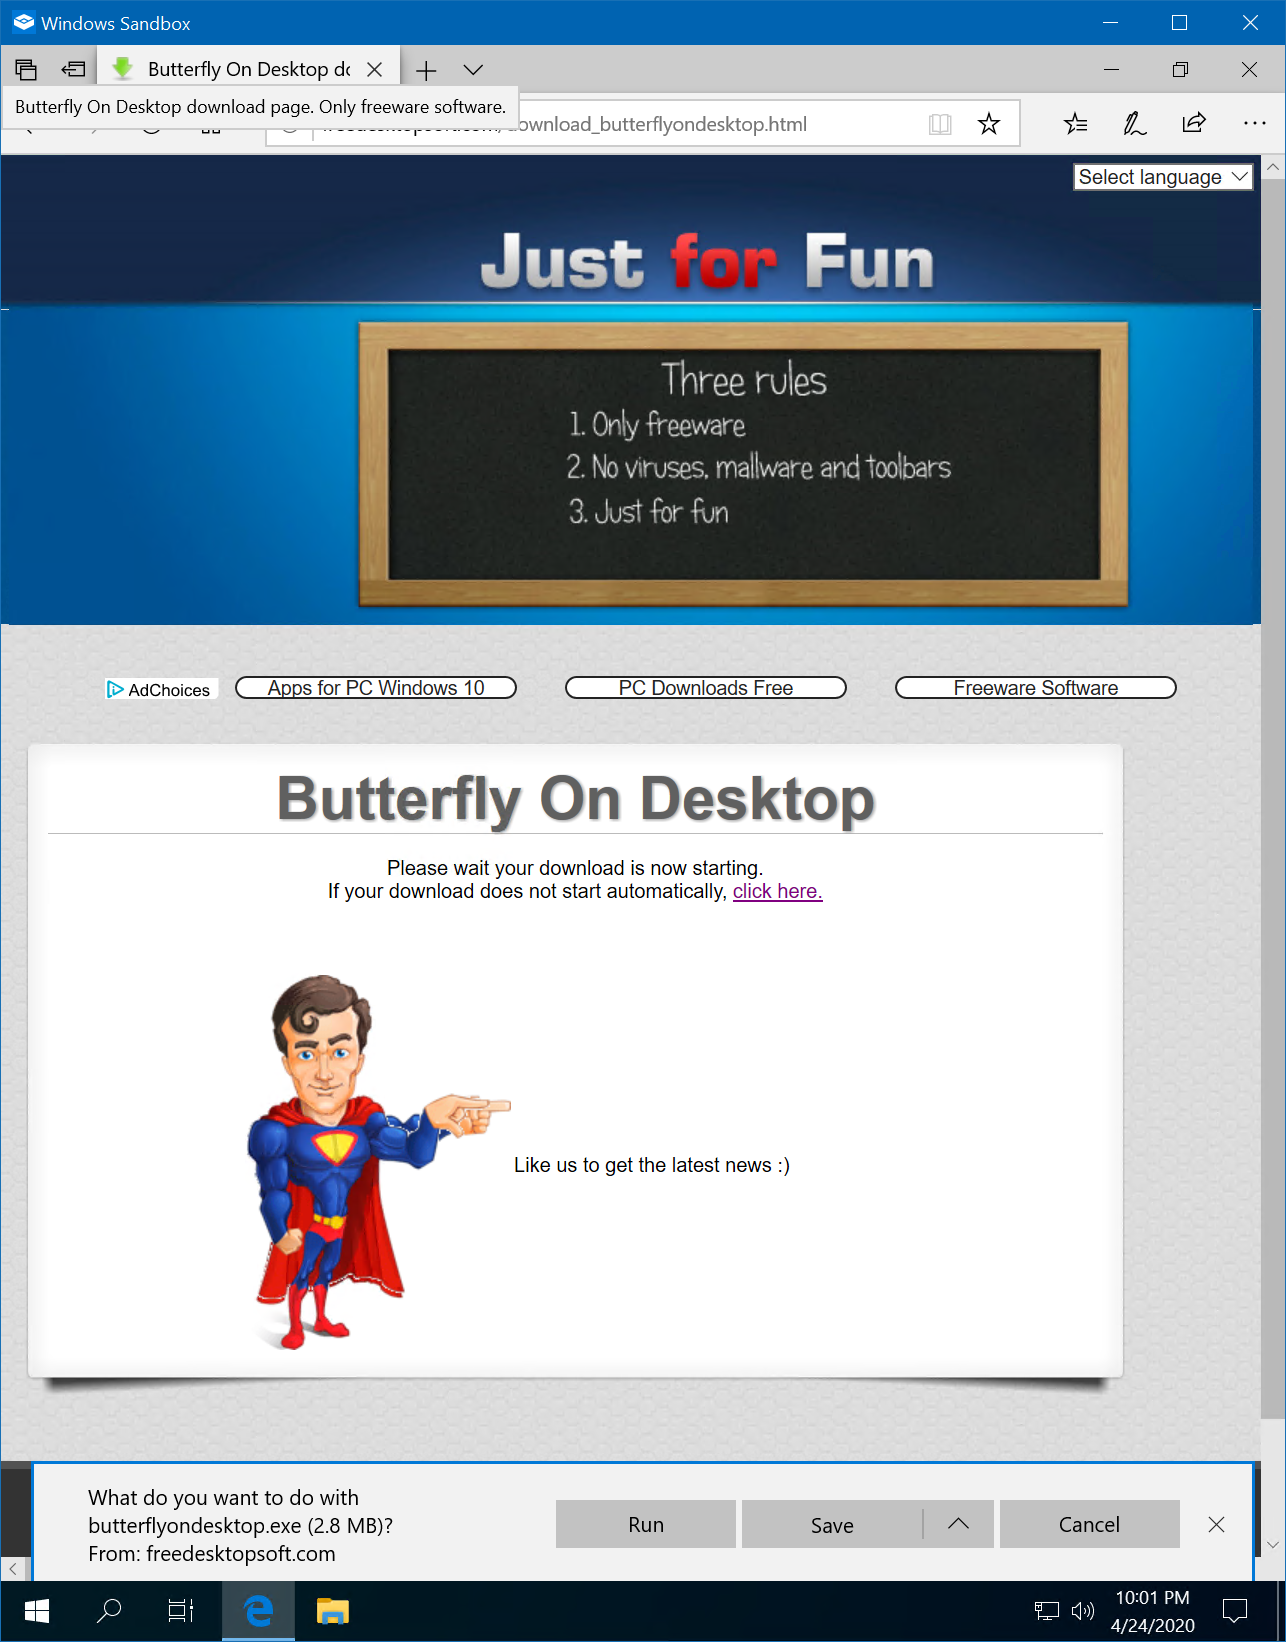
<p>I found an interesting application ‘Butterfly On Desktop’ here: http://freedesktopsoft.com/</p>

<p><img src="/assets/images/posts/windows-sandbox-image-11.png" alt="Butterfly On Desktop" /></p>

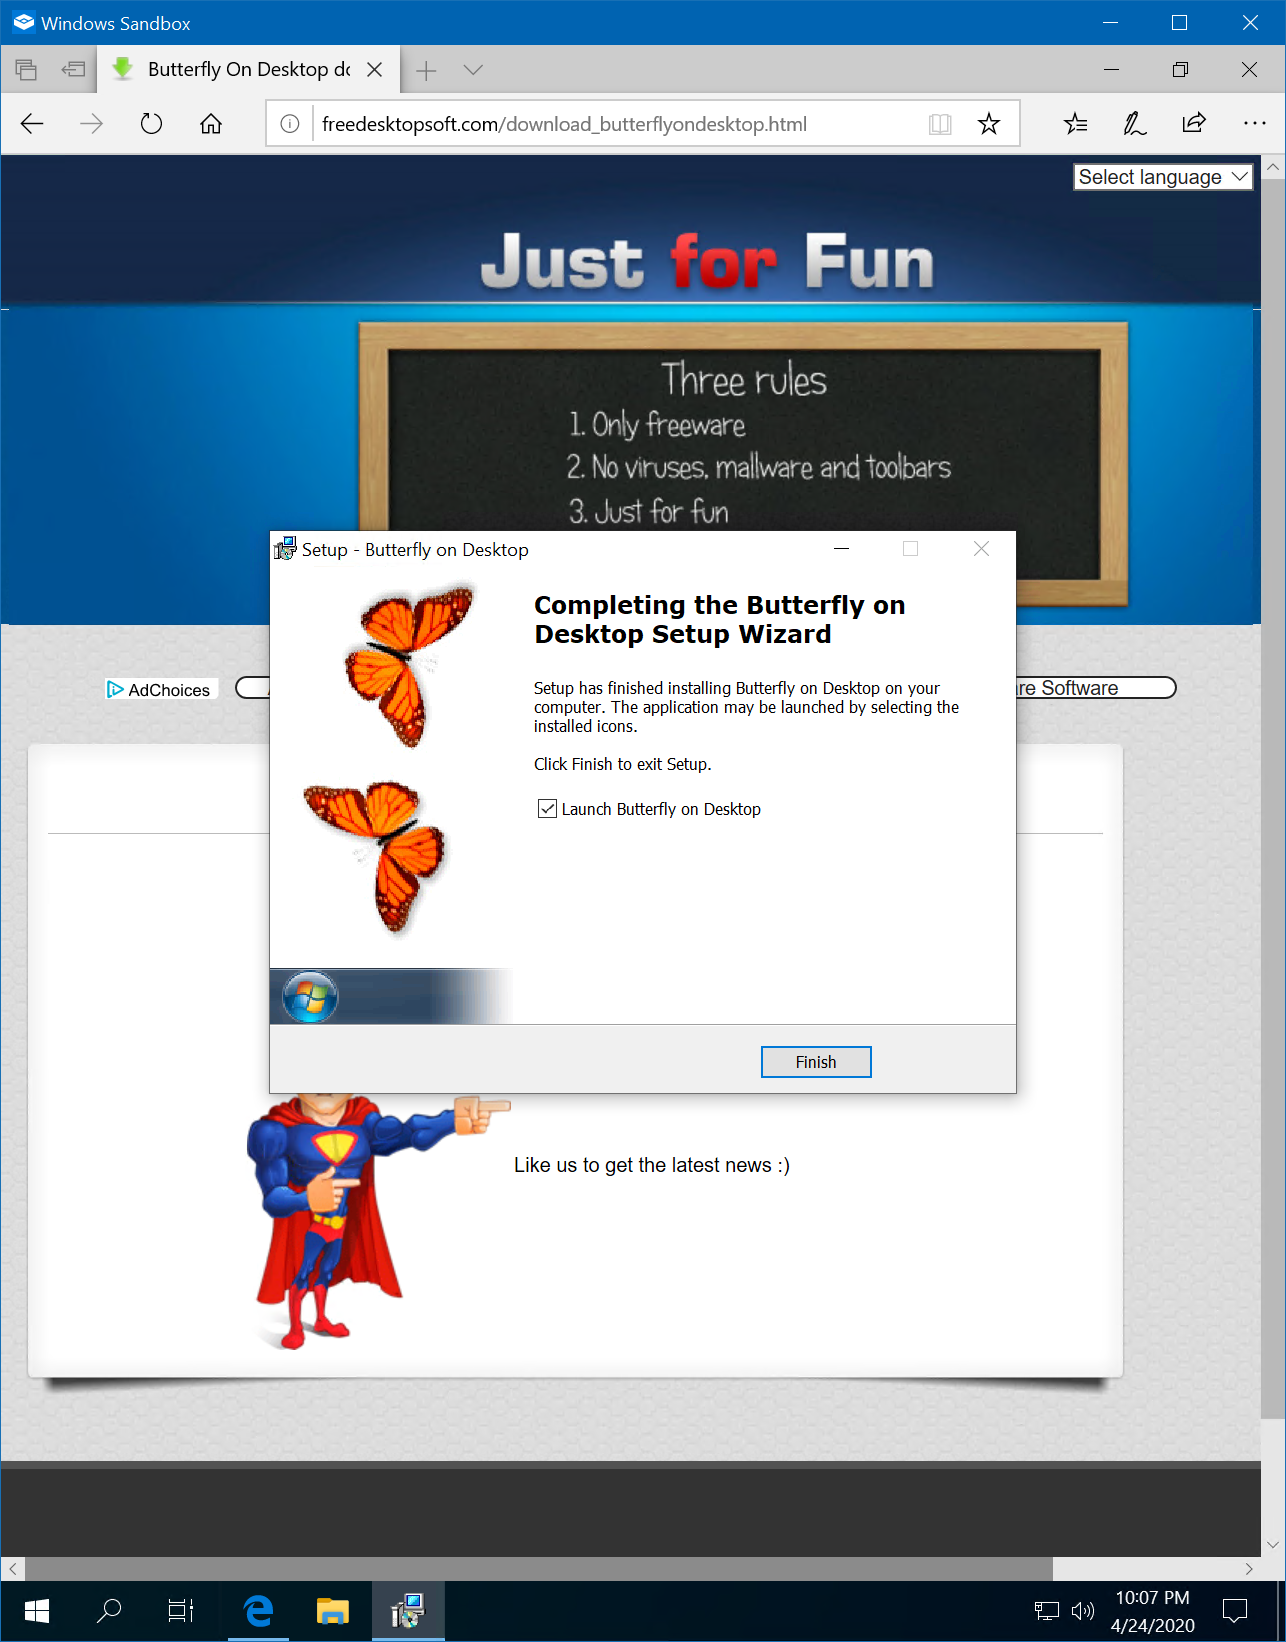
<p>The app didn’t have a valid security certificate - but thanks to Windows Sandbox we can safely run it. Disable the network as an extra safety step, install the app, and launch it.</p>

<p><img src="/assets/images/posts/windows-sandbox-image-12.png" alt="Running the app in Windows Sandbox" /></p>

<p>And, yeesss!</p>

<p><img src="/assets/images/posts/butterflies3.gif" alt="It works" /></p>

<p>Follow me on <a href="https://hachyderm.io/@sachinjoseph">Mastodon</a>!</p>]]></content><author><name></name></author><category term="Windows Developer" /><category term="Windows" /><category term="Sandbox" /><summary type="html"><![CDATA[Running unknown apps is risky:]]></summary></entry></feed>